# Run Kalman Filter
Source: https://methodscenter.mintlify.app/api-reference/endpoint/create
POST /{account_id}/kalman
Processes time series data using a Kalman filter to reduce noise and provide
smoothed predictions. Optionally saves results to the database with a unique identifier.
Submit one or more time series to Luna's Kalman filter. Set `save` to `true`
and include a `unique_identifier` to accumulate historical observations across
requests.
# Check Account Quota
Source: https://methodscenter.mintlify.app/api-reference/endpoint/get
GET /account/quota
Returns the remaining API call quota for your account.
Use this endpoint to monitor your usage and plan accordingly.
Returns the remaining quota units allotted to your account. Poll this endpoint
before launching long-running modelling jobs to make sure you stay within
limits.
# API Reference
Source: https://methodscenter.mintlify.app/api-reference/introduction
Interactive documentation for the Luna Modelling API.
## Welcome to the Luna Modelling API
The Luna Modelling API provides advanced statistical modeling and filtering services designed for educational research and student performance analysis. Built with robust quota management and persistent data storage, our API enables researchers and institutions to process time series data efficiently.
Explore the endpoints below using the live OpenAPI-powered playground.
Switch between request examples to understand stateless and stateful Kalman
filter runs.
## Getting Started
To start using the Luna Modelling API:
1. **Contact us** to obtain your API key and account ID
2. **Include your API key** in the `X-API-Key` header with every request
3. **Monitor your quota** using the `/account/quota` endpoint
4. **Process your data** with our Kalman filtering service
### Base URL
```
Production: https://api.luna-modelling.com/v1
Development: http://localhost:8000/v1
```
## Specification
Download the OpenAPI specification that powers this reference.
## Authentication
All endpoints require an API key via the `X-API-Key` header. The server uses the
key to validate access, enforce quotas, and bind the request to the supplied
`account_id` path parameter when relevant.
```http
X-API-Key:
```
## Available Endpoints
### Account Management
* **`GET /account/quota`** - Check your remaining quota before issuing modelling requests. Use this to monitor usage and plan your API calls accordingly.
### Data Processing
* **`POST /{account_id}/kalman`** - Run Kalman filtering on one or more time series, with optional persistence. The Rauch-Tung-Striebel smoother reduces noise and provides smoothed predictions for student performance data.
## Use Cases
The Luna Modelling API is designed for:
* **Student Performance Prediction** - Filter noisy grade data to identify true performance trends
* **Early Warning Systems** - Detect students at risk of dropout through statistical analysis
* **Longitudinal Studies** - Accumulate and analyze student data over multiple semesters
* **Research Projects** - Process educational data with state-of-the-art filtering techniques
Use the sidebar to jump straight into interactive examples for each endpoint.
# Getting Started
Source: https://methodscenter.mintlify.app/getting-started
University student dropout, particularly in **Science, Technology, Engineering, and Mathematics (STEM)** subjects, represents a significant challenge for both modern economies and the affected individuals. In the German context, for example, approximately **40 percent of students drop out** in the early phase of math studies, a rate considerably higher than the average across all subjects. Traditional models of student attrition often rely on factors that are static or measured only periodically, failing to capture the dynamic, time-sensitive psychological processes that immediately precede a student's decision to quit.
## The Project Solution: A Dynamic, Real-Time Forecasting Approach
Our project introduces a new methodological approach designed to **forecast critical states** related to university student dropout, allowing for **real-time inferences** and the possibility of intervention based on ongoing data collection.
This approach utilizes **Intensive Longitudinal Data (ILD)** and dynamic latent variable model frameworks, such as the **Nonlinear Dynamic Latent Class Structural Equation Model (NDLC-SEM)**. The project focuses on studying individual factors associated with dropout by separating and analyzing two fundamental levels of individual characteristics:
### 1. Inter-Individual Differences
These are relatively **stable personal characteristics or traits** that generally remain consistent across time and situations.
* **Examples:** Cognitive abilities (IQ), gender, and pre-university academic performance.
* **Role in the Model:** These factors describe differences *between* individuals (e.g., why one student is generally more academically prepared than another).
### 2. Intra-Individual Changes (Affective and Cognitive States)
These refer to **changeable psychological states** that vary within an individual over time in response to external experiences and stimuli. Investigating these changes is crucial because they capture the individual psychological processes directly linked to outcomes like dropout.
* **Examples:** Motivational and affective states, goal orientation, fear of failure, subjective feelings of being overwhelmed/stressed, positive and negative affective states (PAN/PAP), and the current intention to quit.
* **Role in the Model:** These factors describe the **longitudinal process** that leads to dropout and are best studied using high-frequency longitudinal designs (ILD) due to their volatile nature. The model specifically forecasts multivariate **intra-individual changes of affective states** and time-dependent class membership (unobserved heterogeneity, or "intention to quit").
## Key Impact and Value Proposition
By applying the proposed forecasting method (using a **Forward Filtering Backward Sampling (FFBS)** method) to ILD gathered from university math students, the project achieved significant predictive results:
* **Prediction of Critical States:** Demonstrated the capability to predict **emerging critical dynamic states** (such as high stress levels or pre-decisional states) related to dropout.
* **The Intervention Window:** For students who eventually dropped out, the model detected the switch to the latent state of "intention to quit" on average at time point *t = 22.2* (approximately the **8th week** of the study program). This critical period is **8 weeks before the actual dropout behavior** was observed (on average at *t = 45.0*).
* **Actionable Insights:** Indicates that **early monitoring and timely interventions** are essential and more likely to be successful. The methodology provides a data-driven basis to identify individuals at risk well in advance of their decision, offering a clear opportunity to intervene and potentially prevent attrition.
* **Model Performance:** The simulation study showed that the method's sensitivity (correctly detecting persons who switched states) was very good (above **0.91**) even with smaller sample sizes, supporting the validity of forecasting individual trajectories and changes over time.
# Methods Center
Source: https://methodscenter.mintlify.app/methods-center
Contact information for the Methods Center at the University of Tübingen.
The Methods Center at the University of Tübingen is an interdisciplinary research institute dedicated to advancing methodological research in the social and behavioral sciences. We work at the intersection of psychometrics and machine learning to develop innovative quantitative and qualitative research methods.
## Contact
**Address:**
Methods Center
Haußerstr. 11
72076 Tübingen, Germany
**Email:**
[sekretariat@mz.uni-tuebingen.de](mailto:sekretariat@mz.uni-tuebingen.de)
**Website:**
[https://uni-tuebingen.de/en/faculties/faculty-of-economics-and-social-sciences/subjects/department-of-social-sciences/methods-center/institute/](https://uni-tuebingen.de/en/faculties/faculty-of-economics-and-social-sciences/subjects/department-of-social-sciences/methods-center/institute/)
# Public API
Source: https://methodscenter.mintlify.app/modelling-api/endpoint
Try different statistical models with Modelling API playground.
Explore the complete API documentation with live examples and interactive playground
The API reference includes comprehensive documentation for all endpoints, authentication guides, and real-world examples to help you integrate the Luna Modelling API into your research projects.
# null
Source: https://methodscenter.mintlify.app/modelling-api/models
## Kalman Filter
The Kalman Filter endpoint processes time series data to reduce noise and extract smooth, accurate predictions. It supports two modes of operation: stateless filtering and stateful filtering with persistent data storage.
## Endpoint
```
POST /api/v1/{account_id}/kalman
```
**Authentication**: Required (API Key via `X-API-Key` header)
**Quota**: Consumes 1 quota unit per request
## Input Schema
### KalmanInput
| Field | Type | Required | Description |
| ------------------- | --------------------- | --------------------- | ----------------------------------------------------------------------------- |
| `results` | `array[array[float]]` | Yes | A 2D array where each inner list contains time series values |
| `save` | `boolean` | No (default: `false`) | Whether to save the data to the database for cumulative processing |
| `unique_identifier` | `string` | Conditional | Required when `save` is `true`. A unique identifier for grouping related data |
### Validation Rules
* When `save` is `true`, `unique_identifier` **must** be provided
* Each inner array in `results` must contain at least one value
* All values must be valid floating-point numbers
## Operation Modes
### Mode 1: Stateless Filtering (Without ID)
**Use Case**: Process a single batch of time series data without persistence.
**Characteristics**:
* `save`: `false`
* `unique_identifier`: Not required (can be `null` or omitted)
* Data is **not stored** in the database
* Filters only the provided data in the current request
* Ideal for one-off analysis or real-time processing
**Example Request**:
```json
{
"results": [[10.2, 10.5, 10.1, 9.8, 10.3, 10.0, 9.9, 10.4]],
"save": false
}
```
**Behavior**:
1. Accepts the input time series data
2. Applies Kalman filtering to the provided data
3. Returns filtered results, raw state estimates, and smoothed state estimates
4. Does **not** persist any data to the database
***
### Mode 2: Stateful Filtering (With ID)
**Use Case**: Accumulate and process historical data over time for a specific identifier.
**Characteristics**:
* `save`: `true`
* `unique_identifier`: **Required** (e.g., `"sensor-001"`, `"user-123"`)
* Data **is stored** in the database with the provided identifier
* Processes **all historical data** associated with the identifier, including the current request
* Ideal for tracking trends over time, cumulative analysis, or multi-session processing
**Example Request**:
```json
{
"results": [[10.2, 10.5, 10.1, 9.8, 10.3]],
"save": true,
"unique_identifier": "sensor-001-2024"
}
```
**Behavior**:
1. Saves the incoming data to the database with the `unique_identifier`
2. Retrieves **all previous data** saved with the same `unique_identifier` for the account
3. Combines all historical data (ordered by creation time)
4. Applies Kalman filtering to the **complete dataset**
5. Returns filtered results based on all available data
**Important Notes**:
* The filter processes data cumulatively, so each request includes all previous data with the same identifier
* Results will change over time as more data is added
* This is useful for progressive refinement of predictions as more observations become available
***
## Data Format
### Expected Input Format
The `results` field must be a **2D array** (array of arrays). Each inner array represents a sequence of time series observations.
#### Single Time Series
```json
{
"results": [[10.2, 10.5, 10.1, 9.8, 10.3]]
}
```
This represents a single time series with 5 observations.
#### Multiple Time Series (Rows)
```json
{
"results": [
[10.2, 10.5, 10.1],
[9.8, 10.3, 10.0],
[9.9, 10.4, 10.2]
]
}
```
This represents 3 separate time series, each with 3 observations. The Kalman filter processes these as sequential observations in the order provided.
#### Real-World Example: Sensor Data
```json
{
"results": [[23.5, 23.7, 23.4, 23.6, 23.8, 23.9, 23.5]],
"save": true,
"unique_identifier": "temperature-sensor-001"
}
```
Temperature readings from a sensor over 7 time points, saved for cumulative tracking.
***
## Output Schema
### KalmanOutput
| Field | Type | Description |
| --------------- | --------------------- | ------------------------------------------------------------------------------ |
| `filtered_data` | `array[float]` | The filtered time series values (predictions) after applying the Kalman filter |
| `raw_state` | `array[float]` | The raw state estimates from the forward pass of the Kalman filter |
| `smooth_state` | `array[float]` | The smoothed state estimates from the backward smoothing pass (RTS smoother) |
| `input_data` | `array[array[float]]` | Echo of the original input data from the request |
### Example Response
```json
{
"filtered_data": [10.2, 10.35, 10.25, 10.02, 10.15, 10.08, 10.01, 10.22],
"raw_state": [10.2, 10.35, 10.25, 10.02, 10.15, 10.08, 10.01, 10.22],
"smooth_state": [10.2, 10.33, 10.27, 10.05, 10.13, 10.09, 10.03, 10.2],
"input_data": [[10.2, 10.5, 10.1, 9.8, 10.3, 10.0, 9.9, 10.4]]
}
```
***
## Kalman Filter Algorithm
The Luna API uses a **Rauch-Tung-Striebel (RTS) smoother**, which consists of two passes:
### 1. Forward Pass (Prediction + Update)
For each observation:
1. **Predict**: Estimate the next state based on the current state
2. **Update**: Correct the prediction using the actual observation
**Output**: `raw_state` - state estimates from the forward pass
### 2. Backward Pass (Smoothing)
After the forward pass, the algorithm runs backward through the data to refine estimates using future observations.
**Output**: `smooth_state` - refined state estimates
### Model Parameters
The filter uses the following matrices (defined in `modelling/constants.py`):
* **F** (State Transition Matrix): `[[1]]` - assumes state remains constant
* **H** (Observation Matrix): 28x1 matrix mapping latent state to observations
* **Q** (Process Noise Covariance): `[[0.1001]]` - system dynamics noise
* **R** (Observation Noise Covariance): 28x28 matrix - measurement noise
* **x0** (Initial State): `[[0]]` - starting state estimate
***
## Use Cases
### Use Case 1: Real-Time Sensor Filtering
**Scenario**: Filter noisy sensor data in real-time without storing history.
```bash
curl -X POST "http://localhost:8000/api/v1/1/kalman" \
-H "X-API-Key: your-api-key" \
-H "Content-Type: application/json" \
-d '{
"results": [[22.1, 22.5, 22.3, 22.7, 22.4]],
"save": false
}'
```
### Use Case 2: Weekly Data Accumulation
**Scenario**: Submit weekly data and process it cumulatively over time.
**Week 1**:
```json
{
"results": [[10.2, 10.5, 10.1, 9.8, 10.3]],
"save": true,
"unique_identifier": "user-123-sensor"
}
```
**Week 2**:
```json
{
"results": [[10.0, 9.9, 10.4, 10.2, 10.1]],
"save": true,
"unique_identifier": "user-123-sensor"
}
```
The second request will process **all 10 observations** (5 from Week 1 + 5 from Week 2).
### Use Case 3: Device-Specific Tracking
**Scenario**: Track data from multiple devices separately.
**Device A**:
```json
{
"results": [[23.5, 23.7, 23.4]],
"save": true,
"unique_identifier": "device-A"
}
```
**Device B**:
```json
{
"results": [[18.2, 18.5, 18.3]],
"save": true,
"unique_identifier": "device-B"
}
```
Each device maintains its own data history.
***
## Error Responses
### 400 Bad Request
**Missing Identifier**:
```json
{
"detail": "unique_identifier is required when save is True"
}
```
**Invalid Data**:
```json
{
"detail": "Input data must contain non-empty lists of observations"
}
```
### 403 Forbidden
**Quota Exceeded**:
```json
{
"detail": "Quota exceeded. Please upgrade your plan."
}
```
### 404 Not Found
**Account Mismatch**:
```json
{
"detail": "Account not found."
}
```
### 500 Internal Server Error
**Processing Error**:
```json
{
"detail": "Error processing Kalman filter: "
}
```
***
## Data Storage
When `save` is `true`, data is stored in the `data` table with the following structure:
| Column | Type | Description |
| ------------------- | --------- | ------------------------------------------ |
| `id` | Integer | Auto-generated primary key |
| `unique_identifier` | String | The identifier provided in the request |
| `data` | JSONB | The raw time series data (`results` array) |
| `account_id` | Integer | Foreign key to the account |
| `created_at` | Timestamp | When the data was saved |
### Data Retrieval
When processing with `save=true`, the service:
1. Saves the new data with the current timestamp
2. Queries all records matching the `unique_identifier` and `account_id`
3. Orders results by `created_at` (chronological order)
4. Flattens all data arrays into a single combined dataset
5. Applies filtering to the complete dataset
***
## Best Practices
### 1. Choose the Right Mode
* Use **stateless mode** (`save=false`) for:
* One-time analysis
* Real-time processing without history
* Testing and debugging
* Use **stateful mode** (`save=true`) for:
* Longitudinal studies
* Progressive data collection
* Multi-session tracking
### 2. Identifier Naming Conventions
Use descriptive, hierarchical identifiers:
* `sensor-{device_id}-{location}`
* `user-{user_id}-{metric_type}`
* `experiment-{exp_id}-week-{week_number}`
### 3. Data Quality
* Ensure consistent sampling rates
* Handle missing data before submission (or use NaN values, which the filter handles)
* Validate data ranges to avoid extreme outliers that could destabilize the filter
### 4. Quota Management
* Monitor your quota using `GET /api/v1/account/quota`
* Each Kalman filter request consumes **1 quota unit**, regardless of data size
* Plan data submission frequency according to your quota allocation
***
## Technical Details
### Missing Value Handling
The Kalman filter automatically handles missing values (NaN):
* If the first observation is missing, it initializes with a default value of `2`
* For subsequent missing values, it samples from the last observed state distribution
* Missing values are imputed using the predicted state before updating
### Numerical Stability
The filter uses:
* **Joseph form** covariance update for numerical stability
* Matrix inversion via `np.linalg.inv` (ensure observations are well-conditioned)
* Covariance matrices are maintained as positive definite throughout
### Performance Considerations
* **Stateless mode**: Processing time is O(n) where n = number of observations
* **Stateful mode**: Processing time is O(N) where N = total historical observations
* Large cumulative datasets may increase processing time and quota consumption
***
## Related Endpoints
* **Check Quota**: `GET /api/v1/account/quota` - Monitor remaining API calls
* **Health Check**: `GET /api/v1/health` - Verify API availability
***
## Example Workflow
```bash
# 1. Check your quota
curl -X GET "http://localhost:8000/api/v1/account/quota" \
-H "X-API-Key: your-api-key"
# 2. Submit initial data with identifier
curl -X POST "http://localhost:8000/api/v1/1/kalman" \
-H "X-API-Key: your-api-key" \
-H "Content-Type: application/json" \
-d '{
"results": [[10.2, 10.5, 10.1, 9.8, 10.3]],
"save": true,
"unique_identifier": "sensor-001"
}'
# 3. Add more data later (cumulative processing)
curl -X POST "http://localhost:8000/api/v1/1/kalman" \
-H "X-API-Key: your-api-key" \
-H "Content-Type: application/json" \
-d '{
"results": [[10.0, 9.9, 10.4]],
"save": true,
"unique_identifier": "sensor-001"
}'
# 4. Process different data without saving
curl -X POST "http://localhost:8000/api/v1/1/kalman" \
-H "X-API-Key: your-api-key" \
-H "Content-Type: application/json" \
-d '{
"results": [[15.2, 15.5, 15.1]],
"save": false
}'
```
***
## Summary
The Kalman Filter model provides flexible time series processing with two distinct modes:
| Feature | Stateless (`save=false`) | Stateful (`save=true`) |
| ----------------------- | ------------------------ | -------------------------------- |
| **Identifier Required** | No | Yes |
| **Data Persistence** | No | Yes |
| **Processing Scope** | Current request only | All historical data with same ID |
| **Use Case** | One-time filtering | Cumulative tracking |
| **Database Impact** | None | Stores data in `data` table |
Choose the appropriate mode based on your application requirements and data workflow.
# null
Source: https://methodscenter.mintlify.app/modelling-api/overview
# Luna Modelling API
## Overview
Luna Modelling API is an advanced modelling and prediction service that provides sophisticated statistical filtering capabilities for time series data. The API specializes in Kalman filtering, enabling users to process noisy time series data and extract smooth, accurate estimates of underlying trends.
## Architecture
```
┌─────────────┐
│ Client │
└──────┬──────┘
│ API Key Authentication
▼
┌─────────────────────────────────────┐
│ Luna Modelling API │
│ ┌──────────────────────────────┐ │
│ │ FastAPI Application │ │
│ │ - CORS Middleware │ │
│ │ - API Key Verification │ │
│ │ - Quota Management │ │
│ └──────────────────────────────┘ │
│ │ │
│ ┌─────────┼──────────┐ │
│ ▼ ▼ ▼ │
│ ┌────┐ ┌────────┐ ┌───────┐ │
│ │Health│ │Kalman │ │Account│ │
│ │Route │ │Filter │ │Route │ │
│ └────┘ └────┬───┘ └───────┘ │
│ │ │
│ ▼ │
│ ┌─────────────────────┐ │
│ │ Kalman Filter Engine│ │
│ │ - Forward Pass │ │
│ │ - Smoothing Pass │ │
│ └─────────────────────┘ │
└───────────────┬─────────────────────┘
│
▼
┌───────────────┐
│ PostgreSQL │
│ Database │
│ - Accounts │
│ - Data Store │
└───────────────┘
```
## Key Concepts
### Account System
The API uses an account-based authentication and authorization system. Each account has the following attributes:
* **Account Name**: A unique identifier for the account
* **API Key**: A UUID-based key used for authentication (passed in the `X-API-Key` header)
* **Quota**: The number of API calls remaining for the account
Accounts are authenticated via API key on every request, and the quota is automatically decremented with each successful API call.
### Quota Management
Quota is a critical concept in the Luna Modelling API:
* Each account has a finite quota of API calls
* Every successful request to processing endpoints (e.g., Kalman filter) consumes 1 quota unit
* The quota check is performed atomically before processing to prevent race conditions
* When quota reaches 0, the API returns a `403 Forbidden` error
* The `/account/quota` endpoint allows users to check their remaining quota without consuming it
### Kalman Filtering
The core functionality of the API is Kalman filtering for time series data:
* **Input**: Multi-dimensional time series data as nested arrays
* **Processing**:
* Forward pass: Predicts and corrects state estimates
* Smoothing pass: Refines estimates using all available data
* **Output**:
* Filtered data (predictions)
* Raw state estimates
* Smoothed state estimates
**Optional Data Persistence**: When the `save` parameter is set to `true`, the API stores the input data with a unique identifier and processes all historical data for that identifier, enabling cumulative analysis over time.
## Prerequisites
Before installing and running Luna Modelling API, ensure you have the following:
* **Python**: Version 3.10 or higher
* **PostgreSQL**: Version 12 or higher
* **pip**: Python package installer
* **Virtual Environment** (recommended): `venv` or `virtualenv`
### System Dependencies
* **PostgreSQL Development Headers**: Required for `psycopg2-binary`
* Ubuntu/Debian: `sudo apt-get install libpq-dev`
* macOS: `brew install postgresql`
* Windows: Included with PostgreSQL installation
## Installation
### 1. Clone the Repository
```bash
git clone
cd luna_modelling_api
```
### 2. Create a Virtual Environment
```bash
python -m venv venv
source venv/bin/activate # On Windows: venv\Scripts\activate
```
### 3. Install Dependencies
```bash
pip install -r requirements.txt
```
### 4. Configure Environment Variables
Create a `.env` file in the project root with the following configuration:
```env
# API Configuration
API_V1_PREFIX=/api/v1
PROJECT_NAME=Luna Modelling API
BACKEND_CORS_ORIGINS=["http://localhost:3000"]
# Database Configuration
POSTGRES_USER=your_db_user
POSTGRES_PASSWORD=your_db_password
POSTGRES_SERVER=localhost
POSTGRES_PORT=5432
POSTGRES_DB=luna_db
DB_SCHEMA=luna_modelling
```
### 5. Set Up the Database
#### Create the Database
```bash
# Connect to PostgreSQL
psql -U postgres
# Create the database
CREATE DATABASE luna_db;
```
#### Run Migrations
```bash
# Initialize Alembic (if not already done)
alembic init alembic
# Run migrations to create tables
alembic upgrade head
```
### 6. Create an Initial Account (Optional)
You can manually create an account in the database or use a script to seed initial data:
```sql
INSERT INTO accounts (account_name, api_key, quota)
VALUES ('test_account', gen_random_uuid(), 1000);
```
## Running the API
### Development Mode
Start the API server with auto-reload enabled:
```bash
uvicorn main:app --reload --host 0.0.0.0 --port 8000
```
### Production Mode
For production deployment:
```bash
uvicorn main:app --host 0.0.0.0 --port 8000 --workers 4
```
### Docker Deployment (Optional)
If you have a Dockerfile:
```bash
docker build -t luna-modelling-api .
docker run -p 8000:8000 --env-file .env luna-modelling-api
```
## API Documentation
Once the API is running, you can access the interactive documentation:
* **Swagger UI**: [http://localhost:8000/docs](http://localhost:8000/docs)
* **ReDoc**: [http://localhost:8000/redoc](http://localhost:8000/redoc)
* **OpenAPI Specification**: [http://localhost:8000/api/v1/openapi.json](http://localhost:8000/api/v1/openapi.json)
## Available Endpoints
### Root
* `GET /` - Welcome message and API information
### Health
* `GET /api/v1/health` - Health check endpoint
### Account
* `GET /api/v1/account/quota` - Check remaining quota (requires API key)
### Kalman Filter
* `POST /api/v1/{account_id}/kalman` - Apply Kalman filtering to time series data (requires API key, consumes quota)
## Authentication
All protected endpoints require an API key to be passed in the request headers:
```bash
curl -H "X-API-Key: your-api-key-uuid" \
http://localhost:8000/api/v1/account/quota
```
## Example Usage
### Check Quota
```bash
curl -X GET "http://localhost:8000/api/v1/account/quota" \
-H "X-API-Key: your-api-key"
```
### Process Kalman Filter
```bash
curl -X POST "http://localhost:8000/api/v1/1/kalman" \
-H "X-API-Key: your-api-key" \
-H "Content-Type: application/json" \
-d '{
"results": [[10.2, 10.5, 10.1, 9.8, 10.3]],
"save": false
}'
```
### Process and Save Data
```bash
curl -X POST "http://localhost:8000/api/v1/1/kalman" \
-H "X-API-Key: your-api-key" \
-H "Content-Type: application/json" \
-d '{
"results": [[10.2, 10.5, 10.1, 9.8, 10.3]],
"save": true,
"unique_identifier": "sensor_001"
}'
```
## Project Structure
```
luna_modelling_api/
├── api/
│ └── routes/ # API route handlers
│ ├── account.py # Account and quota endpoints
│ ├── health.py # Health check
│ └── kalman.py # Kalman filter endpoints
├── core/
│ ├── config.py # Configuration settings
│ ├── database.py # Database connection
│ └── deps/ # Dependency injection
│ ├── check_api_key.py # API key verification
│ └── check_quota.py # Quota management
├── models/ # SQLAlchemy models
│ ├── account.py # Account model
│ └── data.py # Data storage model
├── schemas/ # Pydantic schemas
│ ├── account.py # Account schemas
│ └── kalman.py # Kalman I/O schemas
├── services/ # Business logic
│ └── kalman.py # Kalman filter processing
├── modelling/ # Statistical models
│ ├── kalman_filter.py # Kalman filter implementation
│ └── constants.py # Model constants
├── main.py # Application entry point
├── requirements.txt # Python dependencies
└── .env # Environment variables (not in git)
```
## Development
### Running Tests
```bash
pytest
```
### Code Formatting
```bash
# Using black
black .
# Using isort
isort .
```
### Database Migrations
```bash
# Create a new migration
alembic revision --autogenerate -m "description"
# Apply migrations
alembic upgrade head
# Rollback migration
alembic downgrade -1
```
## Troubleshooting
### Database Connection Issues
* Verify PostgreSQL is running: `pg_isready`
* Check credentials in `.env` file
* Ensure database exists: `psql -l`
### API Key Authentication Failures
* Verify the API key exists in the `accounts` table
* Ensure the `X-API-Key` header is correctly formatted
* Check for UUID formatting (no quotes, proper format)
### Quota Exceeded Errors
* Check remaining quota: `GET /api/v1/account/quota`
* Update quota in database if needed: `UPDATE accounts SET quota = 1000 WHERE id = 1;`
## Support
For issues, questions, or contributions, please refer to the project repository or contact the development team.
## License
\[Specify your license here]
# Empirical Results & Intervention
Source: https://methodscenter.mintlify.app/research/empirical-results-and-intervention
## 1. Characteristics of the Latent Dropout States
The application of the NDLC-SEM allowed for the separation of two **discrete latent states**,\
$s = 1$ (no intention to quit) and $s = 2$ (intention to quit), based on distinct response patterns across seven continuous affective and cognitive scales.
### Intention to Quit ($s = 2$) Profile
Students who transitioned to the latent state $s = 2$ exhibited **consistently higher values** across all seven affective/cognitive scales.\
This profile characterizes students with:
* Higher **stress levels**
* Stronger **fear of failure**
* Perceived **overinvestment of time**
* Pronounced **negative affective states (PAN)**
These patterns clearly align with an emerging **intention to quit**.
### Persistent Dynamics in $s = 2$
The autoregressive coefficients ($\mathbf{B}_{1is}$) were **larger under $s = 2$** than under $s = 1$ (except for the “time investment” scale).\
This indicates that students intending to quit display **stronger, more self-reinforcing autoregressive patterns**, suggesting persistent negative feedback loops in affective and cognitive processes.
### Role of Cognitive Skills (IQ)
Baseline cognitive ability ($\eta_{2i}$) showed strong predictive power for within-level scales when students were in state $s = 1$.\
Higher IQ scores corresponded to **lower stress** and **more stable motivational states**.
To reflect the *Rubicon model* of action, the **return probability** from the “intention to quit” state back to “no intention to quit” was **constrained**:
$$
P_{12} \sim \text{unif}(0.0, 0.1)
$$
The estimated mean value was:
$$
P_{12} = 0.097
$$
indicating that individuals rarely and only **slowly return** to the no-intention state once the quitting intention is formed.
***
## 2. Predictive Factors and the Markov Switching Model
The parameters of the **Markov switching model** identified critical predictors for the transition from $s = 1$ to $s = 2$.
### Primary Predictors ($\gamma_3$)
The transition was primarily driven by:
* **Negative Affect (PAN)**
* **Fear of Failure**
Thus, the **dynamic affective states** and **expectation of failure** are the key determinants of entering the dropout-intention state.
### Cross-Level Effects ($\gamma_4$)
The interaction between baseline cognitive skills (IQ, $\eta_{2i}$) and within-level states ($\mathbf{\eta}_{1i,t-1}$) was **negligible** ($\gamma_4 \approx 0$).\
This shows that while IQ stabilizes affect in $s = 1$, it **does not directly prevent** the switch to $s = 2$, which is primarily emotion-driven.
***
## 3. Establishing the Intervention Window
The most practically relevant finding was the identification of an **intervention window** that precedes actual dropout by several weeks.
* **Critical State Timing:**\
The transition to “intention to quit” ($s = 2$) occurred, on average, at
$$
t = 22.2 \; (\text{SD} = 6.5)
$$
corresponding to approximately the **8th week** of the semester.
* **Actual Dropout Timing:**\
Dropout behavior occurred on average at
$$
t = 45.0 \; (\text{SD} = 11.9)
$$
corresponding to the **16th week**.
* **Lead Time for Intervention:**\
The **forecasted state switch occurred about 8 weeks before** the actual dropout behavior.
* **Intervention Implication:**\
The period around **$t = 22.2$** represents a **critical monitoring point** for identifying and supporting at-risk students.
***
## 4. Overall Student Status and Forecasting Extent
At the end of the observation period ($t = 50$):
* **36.1%** of students had **actually dropped out**.
* The model classified **73.8%** of students as either having dropped out or belonging to the latent class $s = 2$.
* When the forecast was **extended by 5 additional time points**, the proportion predicted to develop dropout intentions rose to **40.2%**, suggesting a **continued increase in risk** beyond the observed period.
***
## 5. Robustness and Performance (Simulation Study)
A **simulation study** was conducted to assess the robustness of the **FFBS forecasting procedure** across varying conditions of sample size ($N_1$) and number of measurement occasions ($N_t$).
### Sensitivity
The model achieved **high sensitivity (> 0.91)** across all conditions.\
This means that individuals who switched states were reliably detected — even for forecasted time points.
### Specificity
Specificity was **lower** in the forecast period, ranging between **0.53–0.70**, indicating a **slight over-prediction** of dropout risk (progressive classification).\
However, **specificity improved significantly** when the sample size increased from $N_1 = 25$ to $N_1 = 50$.
### Forecast Precision
Forecast precision was strongly dependent on the **number of measurement occasions ($N_t$)**:
* With $N_t = 50$, the model achieved **lower quadratic score values** ($\delta_h$), indicating **higher precision**.
* With $N_t = 25$, forecast variance and uncertainty increased.
### Forecast Interval Width
Forecast interval (FI) width **increased with longer forecasting horizons**, forming a **megaphone pattern**.\
However, **increasing both $N_t$ and $N_1$** reduced FI width substantially.
### Coverage Rates
The **95% forecast interval coverage** was slightly below nominal, at **88–90%**.\
This deviation is attributed to the model’s **tendency to over-classify** students into the risk state ($s=2$).
***
> **Summary:**\
> The empirical findings from the SAM study confirm the NDLC-SEM + FFBS framework’s ability to:
>
> * Accurately forecast **latent psychological state transitions**
> * Identify **precise intervention windows** for dropout prevention
> * Achieve robust predictive performance across different sampling and time configurations
>
> Together, these results provide a foundation for **data-driven, early-warning systems** in higher education, capable of detecting and addressing dropout risk dynamically.
# Future (LLM-based Work)
Source: https://methodscenter.mintlify.app/research/future
# Roadmap
Describe the planned LLM-related initiatives, including exploratory studies and anticipated deliverables.
## Research Questions
List the open questions or hypotheses the team wants to investigate with LLM tooling.
## Collaboration Opportunities
# Research Design
Source: https://methodscenter.mintlify.app/research/research-design
## 1. The Context of Urgency in STEM Dropout
The research targets the critical issue of university student dropout from **Science, Technology, Engineering, and Mathematics (STEM)** fields, which represents an important issue for both modern economies and individuals.
The study focuses specifically on **mathematics students** at a German university. This focus is motivated by the severe attrition rates in the subject — approximately **40% of students drop out** in the early phase of math studies in Germany, a rate considerably higher than the **33% average** across all subjects.
Since the majority of students drop out during their first semester, large introductory courses, such as **calculus** and algebra, were considered suitable contexts for this examination. The cohort attending the calculus lecture during the **2017/2018 winter semester** was deemed prototypical for the general phenomenon.
***
## 2. Theoretical Foundation: The Procedural Nature of Dropout
The research design builds on the consensus that the **university dropout decision has a procedural nature**, requiring longitudinal study designs to model it appropriately.
To capture this complex process, the study simultaneously analyzed two fundamental types of individual factors, recognizing that stable characteristics alone often fail to capture the **critical psychological processes** leading to dropout.
***
### 2.1 Inter-Individual Differences (Stable Trait Level)
This level comprises **relatively stable personal characteristics or traits** that remain consistent over time and across situations.\
These factors describe differences *between* individuals.
**Examples of Inter-Individual Measures:**
* Gender
* Cognitive ability (**IQ**)
* Pre-university academic performance (GPA)
***
### 2.2 Intra-Individual Changes (Volatile State Level)
This level consists of **changeable psychological states** that vary *within* an individual over time in response to external experiences and stimuli.\
Investigating these **intra-individual changes** is central to forecasting because they capture the **dynamic longitudinal process** leading to dropout.
Given their volatility, these states require a **high-frequency longitudinal design**.
**Examples of Intra-Individual Measures:**
* Motivational states
* **Affective states**
* Goal orientation
* **Current intention to quit** the course
The overall model specification integrates these two levels, alongside **latent heterogeneity (latent classes)** and **time-dependent variables**, to represent the dropout process in full dynamic complexity.
***
## 3. Study Setting, Sample, and Participation
The empirical basis for this project is the **SAM (University Dropout in Mathematics)** study.
**Setting:**\
Data were collected from a **first-semester cohort** attending a calculus lecture and tutorial sessions at a German university during the **2017/2018 winter semester**.
**Sample:**
* $N = 122$ students participated in online surveys.
* Participation rate: **67.03%** of the eligible population.
**Sample Characteristics:**
* **Average age:** 19.60 years
* **Gender:** 55 female (45.08%), 66 male (54.09%)
* **Programs:** Mathematics B.Sc., Mathematics B.Ed. (teacher candidates), and Physics B.Sc.
* **Academic background:** Mean GPA (Abitur) = 1.86
***
## 4. Intensive Longitudinal Data (ILD) Collection Methodology
To effectively capture the **volatile state-level changes**, the SAM study implemented a rigorous **ILD framework**, integrating data from three distinct sources across the semester.
***
### 4.1 Source 1: Initial Assessment (Stable Trait Measures)
Conducted during **week 2 of the first semester**, the initial assessment collected **inter-individual characteristics**.
**Measures Included:**
* **Cognitive Abilities (IQ):** German adaptation of the *Culture Fair Intelligence Test Scale 3 (CFT-3)*
* **Academic Performance:**
* German GPA (Abitur)
* Final math grade from school
* Performance on **TIMSS** items
* **Psychosocial Measures:**
* Personality via *BFI-2-XS* (Big Five Inventory short form)
* Locus of Control via *IE-4* scale
* Professional interests via Holland’s *RIASEC* model (*AIST-R*)
* **Affective Baseline:**
* Positive and Negative Affect measured using *PANAS* (PAP/PAN scales)
***
### 4.2 Source 2: High-Frequency Online Surveys (Changeable State Measures)
Beginning **one week after** the initial assessment, the core longitudinal data collection was conducted via **frequent online surveys**.
**Frequency and Duration:**
* $N_t = 50$ measurement occasions
* Spanning **131 days** (\~3 surveys per week)
* Each survey lasted approximately **5 minutes**
* Average participation per student: **20.22 surveys**
**Survey Content:**
* Re-assessed motivational and affective states
* Captured dropout-related factors:
* **Current intention to quit**
* **Fear of failure**
* Feelings of being **overwhelmed** or stressed
* Self-assessed **understanding** of course content
***
### 4.3 Source 3: Outcome and Performance Data
This dataset informed the **criterion variable (dropout)** and supported **latent state estimation**.
**Key Details:**
* **Weekly collection:** Tutorial performance and attendance
* **Dropout identification:** Enabled early detection of dropout events *during the semester*
This design allowed the latent discrete state variable ($S_{it}$), representing the **“intention to quit”**, to be treated as **partially observed** whenever manifest dropout occurred (i.e., if a student quit at time $t$, then $S_{it} = s=2$ was observed).
***
> **Summary:**\
> The SAM Study’s design exemplifies a methodological innovation in educational psychology — leveraging **Intensive Longitudinal Data** to model **dynamic intra-individual change** and predict **critical dropout-related psychological states** in real time.
# Statistical Model
Source: https://methodscenter.mintlify.app/research/statistical-model
## 1. The Core Framework: Nonlinear Dynamic Latent Class SEM (NDLC-SEM)
The forecasting of critical states in the SAM study required innovative techniques to capture the complex, multi-level nature of student dropout.\
The methodological approach relies on the **Nonlinear Dynamic Latent Class Structural Equation Model (NDLC-SEM)** — a flexible Bayesian framework integrated with a modified **Forward Filtering Backward Sampling (FFBS)** algorithm for real-time prediction.
***
### 1.1 Key Capabilities
The NDLC-SEM framework combines the capabilities of several dynamic models to simultaneously address **four essential data structures** for modeling the longitudinal dropout process using **Intensive Longitudinal Data (ILD)**.
It models:
1. **Inter-Individual Differences (Traits):** Stable characteristics (e.g., cognitive abilities).
2. **Intra-Individual Changes (States):** Changeable psychological states (e.g., affective and motivational states).
3. **Unobserved Heterogeneity of Trajectories:** Captured via **time-varying latent classes** following a *hidden Markov process*.
* In this study, these classes represent the discrete latent variable $S_{it}$:
* **$s=1$:** Intention to stay
* **$s=2$:** Intention to quit
4. **Time-Dependent Nonlinearities:** Latent within-person variables predict transition probabilities with nonlinear effects.
The model was implemented in **JAGS 4.2** and executed via the **R2jags** package, using a **Gibbs sampler** for Bayesian estimation.
***
## 2. Model Specification
The model specification outlines how observed variables relate to latent constructs (**measurement models**) and how these latent constructs evolve and interact across levels (**structural models**).
***
### 2.1 Measurement Models
**Within-Level (States – $\mathbf{\eta}_{1it}$):**
Seventeen observed variables ($\mathbf{Y}_{1it}$) operationalize **seven continuous latent within-factors** ($\mathbf{\eta}_{1its}$), representing affective/cognitive states such as stress, fear of failure, and affect balance.
All observed variables were centered and oriented so that higher values indicate stronger *intention to quit*.
The within-level measurement model is consistent across latent states:
$$
\textbf{Equation (1):} \quad (\mathbf{Y}_{1it} \mid S_{it} = s) = \mathbf{\Lambda}_{10}\mathbf{\eta}_{1its} + \mathbf{\varepsilon}_{1it}
$$
Where:
* $\mathbf{Y}_{1it}$ = (17 × 1) vector of observed variables
* $\mathbf{\eta}_{1its}$ = (7 × 1) vector of latent state factors
* $\mathbf{\varepsilon}_{1it}$ = vector of residuals
***
**Between-Level (Traits – $\mathbf{\eta}_{2i}$):**
A single latent construct — *cognitive ability (IQ)* — was modeled using three CFT-3 test items measured at baseline.
$$
\textbf{Equation (2):} \quad \mathbf{Y}_{2i} = \mathbf{\Lambda}_{2}\mathbf{\eta}_{2i} + \mathbf{\varepsilon}_{2i}
$$
Where:
* $\mathbf{Y}_{2i}$ = (3 × 1) vector of observed indicators
* $\mathbf{\eta}_{2i}$ = latent IQ factor
* $\mathbf{\varepsilon}_{2i}$ = uncorrelated residuals
***
### 2.2 Structural Dynamics (Within-Level)
The within-level dynamics were modeled using a **first-order autoregressive process (AR(1))**, specific to the discrete latent class $S_{it}=s$:
$$
\textbf{Equation (3):} \quad (\mathbf{\eta}_{1it} \mid S_{it}=s) = \mathbf{\alpha}_{1is} + \mathbf{B}_{1is}\mathbf{\eta}_{1i,t-1} + \mathbf{\zeta}_{1it}
$$
Where:
* $\mathbf{\eta}_{1i,t-1}$ = latent states at previous time $t-1$
* $\mathbf{\alpha}_{1is}$ = class-specific intercept vector
* $\mathbf{B}_{1is}$ = diagonal matrix of AR(1) effects
* $\mathbf{\zeta}_{1it}$ = innovation term
*Note:* Initial tests showed near-zero cross-lagged effects, justifying a simplified AR(1) structure.
***
### 2.3 Structural Models (Between- and Cross-Level Interactions)
The stable latent trait (IQ, $\mathbf{\eta}_{2i}$) influences both the intercepts and autoregressive dynamics of the latent state processes.
**Intercept Function:**
$$
\textbf{Equation (4):} \quad \mathbf{\alpha}_{1is} = \mathbf{\alpha}_{21s} + \mathbf{\beta}_{2s}\eta_{2i} + \mathbf{\zeta}_{2i}
$$
**AR Coefficients with Cross-Level Moderation:**
$$
\textbf{Equation (5):} \quad \mathbf{B}_{1is} = \mathbf{B}_{1s} + \mathbf{\Omega}_{2s}\eta_{2i}
$$
Here, $\mathbf{\Omega}_{2s}$ allows cognitive ability (IQ) to moderate motivational and self-regulatory state dynamics over time.
***
### 2.4 Markov Switching Model (Transition Probabilities)
The discrete latent state $S_{it}$ evolves according to a **hidden Markov process**, governed by transition probabilities derived via a **logit link function**.
**Probability of Staying in $s=1$ (No Intention to Quit):**
$$
\textbf{Equation (6):} \quad \text{P}(S_{it}=1 \mid S_{i,t-1}=1) = \frac{\exp(\nu_{it}^{11})}{\exp(\nu_{it}^{11}) + 1}
$$
**Logit Function Definition:**
$$
\textbf{Equation (10):} \quad \nu_{it}^{11} = \gamma_{1} + \gamma_{2}\eta_{2i} + \mathbf{\gamma}_{3}\mathbf{\eta}_{1i,t-1} + \mathbf{\gamma}_{4}\mathbf{\eta}_{1i,t-1}\eta_{2i}
$$
**Return Probability (P₁₂):**\
The transition from *intention to quit* ($s=2$) to *intention to stay* ($s=1$) is assumed rare and slow:
$$
P_{12} \sim \text{unif}(0.0, 0.1)
$$
This aligns with the **Rubicon model**, positing that individuals rarely revert once a quitting intention is formed.
***
## 3. Identification of Latent Discrete States
Identifying the latent states ($S_{it}$) as “intention to drop out” involved a confirmatory modeling strategy:
1. **Imposed Constraints:**\
Persons in state $s=2$ constrained to show *higher scores* on all seven negative affect scales.
2. **Predictive Link:**\
Transition probabilities were regressed on affective scales and their interactions with IQ.
3. **Temporal Restrictions:**\
Transitions back to $s=1$ restricted to low probability.
4. **Partial Observation:**\
Dropouts observed during the semester were coded directly as $S_{it}=2$ (manifest dropout).
***
## 4. Forecasting Implementation: Forward Filtering Backward Sampling (FFBS)
Forecasting dynamic latent states is achieved through the **Forward Filtering Backward Sampling (FFBS)** algorithm — a Bayesian sequential estimation method adapted for hidden Markov models (see West & Harrison, 1997).
***
### 4.1 Key Features of the FFBS Adaptation
* Integrates seamlessly with the **Gibbs sampler** (forecasting within estimation loop).
* Handles **latent time-dependent predictors** ($\mathbf{\eta}_{1it}$) driving state transitions.
* Produces **real-time posterior forecasts** for the latent dropout intention states.
***
### 4.2 Core Algorithmic Steps
#### Step 1 — Reformulation (Aspect i.)
Reformulate NDLC-SEM into a **Dynamic Linear Model (DLM)** framework:
* **Observation Equation:**
$$
\mathbf{\eta}_{1jts} = \mathbf{F}_{jt}\mathbf{\theta}_{jts} + \mathbf{v}_{jts}
$$
* **System Equation:**
$$
\mathbf{\theta}_{jts} = \mathbf{G}_{jts}\mathbf{\theta}_{j,t-1,s} + \mathbf{w}_{jts}
$$
***
#### Step 2 — Define Strata (Aspect ii.)
Define **four strata** $(s, s')$ for every consecutive time pair $(t, t-1)$, covering all possible transitions between “stay” and “quit” states.
***
#### Step 3 — Continuous State Prediction (Aspect iii.)
For each stratum, sample latent factor scores, producing four forecast draws:
$$
(\eta_{1jit} \mid (s,s'), D_{t-1})
$$
***
#### Step 4 — Marginal Predictive Density (Aspect iv.)
Compute the mixture of predictive densities across the four strata:
$$
\text{P}(\mathbf{\eta}_{1jit}\mid D_{t-1}) = \sum_{s=1}^{2}\sum_{s'=1}^{2} \left[ \pi_{i}(s,s')p_{i,t-1}(s') \text{P}(\mathbf{\eta}_{1jit}\mid(s,s'),D_{t-1}) \right]
$$
This produces the overall **forecast distribution** of the continuous latent variable.
***
### 4.3 Posterior Updating and Smoothing
After observing $D_t$, priors are updated and the **joint posterior** over model combinations is computed:
$$
p_{it}(s,s') \propto \pi_{i}(s,s')p_{i,t-1}(s')\text{P}(\mathbf{\eta}_{1jit}\mid M_{it}(s), M_{i,t-1}(s'),D_t)
$$
The **smoothed posterior** for each latent state is then:
$$
p_{it}(s) = \sum_{s'=1}^{2} p_{it}(s,s')
$$
***
### 4.4 H-Steps-Ahead Forecasting
For future predictions ($t > N_t$):
* Use last observed posteriors ($t = N_t$).
* Recursively define expected values $\mathbf{a}_{jt}$ and covariance matrices $\mathbf{R}_{jt}$.
* Generate the $H$-step-ahead forecast distribution of latent factors $\mathbf{\eta}_{1jt}$.
***
> **Summary:**\
> The integrated **NDLC-SEM + FFBS** framework enables dynamic, real-time prediction of **latent dropout intentions**, bridging stable cognitive traits and fluctuating emotional-motivational states.\
> It provides a powerful approach to modeling **nonlinear psychological dynamics** in longitudinal educational data.
# Architecture
Source: https://methodscenter.mintlify.app/web-platform/architecture
## System Overview
* **Runtime Stack:** Django REST Framework application served from Docker containers, backed by PostgreSQL, with analytics powered by a custom modelling module.
* **Hosting Pattern:** Container stack deployed on AWS EC2, fronted by Nginx for TLS termination, caching, and static asset delivery.
* **Automation:** Cron-driven background jobs create surveys, execute modelling pipelines, and issue alerts without blocking API requests.
* **Observability:** Application logs streamed via Docker, PostgreSQL introspection through pgAdmin, and health endpoints ready for integration into CloudWatch or Datadog.
## Infrastructure Topology
```mermaid
flowchart LR
A[Student Browser] --> D[Internet]
B[Lecturer Browser] --> D
C[Researcher Tools] --> D
D --> E[Route 53 DNS]
E --> F[AWS Security Group]
F --> G[EC2 Instance]
subgraph EC2[EC2 Instance]
H[Nginx Reverse Proxy] --> I[Django App Server]
I --> J[PostgreSQL Database]
K[pgAdmin] -.-> J
L[django-cron] -.-> I
M[Analytics Engine] -.-> I
I --> M
end
G --> H
```
## Full Stack Request Flow
```mermaid
flowchart LR
A[Next.js Frontend
Vercel] -->|HTTPS API Calls| B[Internet]
B --> C[Route 53 DNS]
C --> D[AWS Security Group]
D --> E[Nginx Reverse Proxy
EC2]
E --> F[Django REST API
Docker Container]
F --> G[PostgreSQL
Database]
H[Background Jobs
django-cron] -.-> F
F -.-> I[Analytics Engine
Kalman Filter]
```
### Nginx Responsibilities
* Terminate HTTPS and enforce secure headers (HSTS, CSP).
* Reverse proxy API traffic to `web` container on port `8000`.
* Serve cached static files from `/var/www/luna/static/` for low latency.
* Expose `/admin` and `/api` under the same domain for simplicity; consider subdomains when scaling.
## Application Layer
| Layer | Responsibilities | Key Components |
| --------------------- | ----------------------------------------------------------------- | -------------------------------- |
| **API Gateway** | REST routing, serializers, authentication, permission enforcement | API endpoints, DRF views |
| **Domain Layer** | User management, course modules, surveys, and forms | Core business logic, data models |
| **Modelling Layer** | Kalman filter computations, analytics persistence, exports | Statistical analysis engine |
| **Cron & Scheduling** | Periodic job orchestration for surveys and analytics | Background job scheduler |
## Request Lifecycle Flow
```mermaid
sequenceDiagram
participant Student as Student
participant Nginx as Nginx Reverse Proxy
participant API as Django API
participant DB as PostgreSQL
participant Cron as Cron Runner
participant Model as Modelling Engine
Student->>Nginx: POST /api/modules/{id}/surveys
Nginx->>API: Forward request
API->>DB: Create survey record (status=ACTIVE)
API-->>Student: 201 Created + survey metadata
Cron->>API: Trigger weekly survey generation job
API->>DB: Insert new survey records
Cron->>Model: Invoke modelling task
Model->>DB: Update results with smoothed metrics
Model-->>API: Model status reported for dashboards
```
## Data Model Overview
### Entity Relationship Diagram
```mermaid
erDiagram
User ||--o{ Student : "extends as"
User ||--o{ Module : "owns/teaches"
University ||--|{ Module : "offers"
University ||--|{ Faculty : "contains"
Module ||--o{ Enrollment : "has"
Student ||--o{ Enrollment : "participates in"
Module ||--o{ Survey : "generates"
Student ||--o{ Survey : "completes"
Form ||--o{ FormResponse : "collects"
Student ||--o{ FormResponse : "submits"
User {
string email
string role
string university
}
Student {
string demographics
string language
string background
}
Module {
string name
string code
string semester
date schedule
string status
}
Enrollment {
date enrolled_date
string status
}
Survey {
int sequence_number
json responses
string completion_status
date submitted_at
}
Form {
string name
json structure
}
FormResponse {
json answers
date submitted_at
string status
}
```
### Core Entities
**University**
* Represents educational institutions
* Contains multiple faculties and departments
* Supports multi-tenant platform architecture
**User**
* Email-based authentication system
* Three roles: Student, Lecturer, Administrator
* Linked to university affiliation
**Student**
* Extended user profile for student participants
* Stores demographic and academic background
* Tracks language preferences and financial support
**Module (Course)**
* Represents academic courses/subjects
* Configurable semester periods (Winter/Summer)
* Password-protected enrollment system
* Scheduled survey deployment days
* Active/Inactive status management
**Enrollment**
* Links students to their enrolled courses
* Prevents duplicate enrollments
* Tracks enrollment timeline
**Survey**
* Time-series survey instances for longitudinal data collection
* Auto-incremented sequence numbers per student
* Flexible JSON structure for diverse question types
* Completion tracking (Completed/Not Completed)
* Lifecycle status (Active/Archived)
**Form Template**
* Reusable questionnaire blueprints
* JSON-based flexible structure
* Created by lecturers and administrators
**Form Response**
* Student submissions to forms
* Tracks completion status and timestamps
* JSON storage for answers
**Faculty**
* Organizational units within universities
* Groups related departments and programs
## Technology Stack
### Backend Framework
* **Django 4.2.5** - Model-View-Template architecture
* **Django REST Framework 3.14.0** - RESTful API design
* **Custom authentication** - Email-based user system
### Database
* **PostgreSQL** - ACID-compliant relational storage
* **JSON fields** - Flexible survey and form content
* **Database adapter** - psycopg2-binary
### API & Documentation
* **OpenAPI/Swagger** - Interactive API documentation (drf-yasg)
* **CORS support** - Cross-origin resource sharing (django-cors-headers)
### Task Scheduling
* **django-cron** - Periodic job execution
* **Survey automation** - Scheduled deployment system
### Configuration & Deployment
* **Environment management** - python-decouple, python-dotenv
* **Containerization** - Docker, Docker Compose
* **Web server** - Nginx (reverse proxy, SSL termination)
### Cloud Infrastructure
* **Compute** - AWS EC2 instances
* **Deployment** - Dockerized application on EC2
* **Networking** - Nginx reverse proxy with SSL/TLS
## Deployment Architecture
```mermaid
flowchart LR
A[Internet] --> B[Route 53 DNS]
B --> C[AWS Security Group]
C --> D[EC2 Instance]
subgraph EC2 Instance
E[Nginx
SSL/TLS] --> F[Luna App
Django]
F <--> G[PostgreSQL
Database]
end
D --> E
```
## Background Processing
1. **Survey Generation** - Runs twice daily; creates upcoming survey records based on module schedule and student enrollment.
2. **Analytics Pipeline** - Ingests completed surveys, executes Kalman smoothing, writes metrics to analytics tables for dashboards.
## Security Architecture
### Authentication & Authorization
* Email-based authentication (no username required)
* Secure password hashing using Django's PBKDF2 algorithm
* Role-based access control (Student, Lecturer, Administrator)
* Session-based authentication framework
### Data Protection
* Environment-based configuration (no hardcoded secrets)
* CORS policy enforcement for API security
* SQL injection prevention via ORM parameterization
* XSS protection through template auto-escaping
### Infrastructure Security
* Container isolation and separation
* Docker bridge network segmentation
* HTTPS/TLS encryption in production (Nginx)
* Database access restricted to internal network
## Related Documentation
* [Overview](./overview.md) - Platform introduction and research context
* [Installation Guide](./installation.md) - Environment setup instructions
* [Student Experience](./student-experience.md) - Student user workflows
* [Lecturer Experience](./lecturer-experience.md) - Lecturer and researcher workflows
# Installation & Open Source
Source: https://methodscenter.mintlify.app/web-platform/installation
Set up the Student Dropout web platform for your environment.
## Prerequisites
Before installing Luna, ensure you have the following installed:
* **Python 3.9+**
* **Docker** and **Docker Compose**
* **PostgreSQL** (for local development without Docker)
* **Git**
## Dependencies
### Core Packages
| Package | Version | Purpose |
| --------------------- | ------- | ------------------ |
| Django | 4.2.5 | Web framework |
| Django REST Framework | 3.14.0 | API development |
| psycopg2-binary | 2.9.7 | PostgreSQL adapter |
| django-cors-headers | 4.2.0 | CORS handling |
| python-decouple | 3.8 | Environment config |
| django-cron | - | Scheduled tasks |
| drf-yasg | - | API documentation |
| numpy | - | Data analysis |
### Additional Dependencies
```
asgiref==3.7.2
pytz==2023.3.post1
sqlparse==0.4.4
typing-extensions==4.7.1
tzdata==2023.3
python-dotenv
```
## Installation Methods
### Method 1: Docker Installation (Recommended)
#### Step 1: Clone Repository
```bash
git clone https://github.com/Luna-DroMo/luna_backend
cd luna_backend
```
#### Step 2: Configure Environment Variables
Create a `.env` file in the project root:
```bash
# Database Configuration
PGHOST=db
PGNAME=postgres
PGUSER=your_username
PGPASSWORD=your_secure_password
PGPORT=5432
# Django Configuration
SECRET_KEY=your_django_secret_key
DEBUG=True
ALLOWED_HOSTS=localhost,127.0.0.1
```
#### Step 3: Build and Start Services
```bash
# Build and start all containers
docker-compose up --build
# Or run in detached mode
docker-compose up -d --build
```
This will start:
* **Web Application** (Port 80 → 8000)
* **PostgreSQL Database** (Port 5432)
* **pgAdmin** (Port 8001)
#### Step 4: Run Database Migrations
```bash
# Apply database migrations
docker-compose exec web python manage.py migrate
# Create migrations if models changed
docker-compose exec web python manage.py makemigrations
```
#### Step 5: Create Superuser
```bash
docker-compose exec web python manage.py createsuperuser
```
Follow prompts to enter:
* Email address
* First name
* Last name
* Password
#### Step 6: Initialize University Data
Access PostgreSQL and create initial university:
```bash
# Connect to database
docker-compose exec db psql -U postgres
# Create university
INSERT INTO core_university (id, name, created_at, updated_at)
VALUES (1, 'University of Tübingen', NOW(), NOW());
```
Or use external tools (DBeaver, pgAdmin) with:
* **Host**: localhost
* **Port**: 5432
* **Database**: postgres
* **Username**: (from .env PGUSER)
* **Password**: (from .env PGPASSWORD)
#### Step 7: Access Application
* **Main Application**: [http://localhost](http://localhost)
* **Admin Portal**: [http://localhost/admin](http://localhost/admin)
* **pgAdmin**: [http://localhost:8001](http://localhost:8001)
* Email: [admin@pgadmin.org](mailto:admin@pgadmin.org)
* Password: admin
### Method 2: Local Python Installation
#### Step 1: Clone and Setup Virtual Environment
```bash
git clone
cd luna_backend
# Create virtual environment
python3.9 -m venv venv
# Activate virtual environment
# On macOS/Linux:
source venv/bin/activate
# On Windows:
venv\Scripts\activate
```
#### Step 2: Install Dependencies
```bash
pip install -r requirements.txt
```
#### Step 3: Configure Environment
Create `.env` file:
```bash
# Database Configuration (Local PostgreSQL)
PGHOST=localhost
PGNAME=luna_db
PGUSER=your_username
PGPASSWORD=your_password
PGPORT=5432
# Django Configuration
SECRET_KEY=your_django_secret_key
DEBUG=True
ALLOWED_HOSTS=localhost,127.0.0.1
```
#### Step 4: Setup PostgreSQL Database
```bash
# Create database
createdb luna_db
# Or via psql
psql -U postgres
CREATE DATABASE luna_db;
```
#### Step 5: Run Migrations
```bash
cd luna
python manage.py migrate
python manage.py createsuperuser
```
#### Step 6: Start Development Server
```bash
python manage.py runserver
```
Access at: [http://localhost:8000](http://localhost:8000)
## Docker Service Management
### View Logs
```bash
# All services
docker-compose logs
# Specific service
docker-compose logs web
docker-compose logs db
# Follow logs
docker-compose logs -f web
```
### Container Access
```bash
# Access web container shell
docker-compose exec web bash
# Access database
docker-compose exec db psql -U postgres
```
### Restart Services
```bash
# Restart all
docker-compose restart
# Restart specific service
docker-compose restart web
docker-compose restart db
```
### Stop Services
```bash
# Stop all containers
docker-compose down
# Stop and remove volumes (careful!)
docker-compose down -v
```
## Database Setup Details
### Docker Compose Configuration
The `docker-compose.yml` defines three services:
```yaml
services:
web: # Django application (Port 80→8000)
db: # PostgreSQL database (Port 5432)
pgadmin: # Database admin interface (Port 8001)
```
### Dockerfile Overview
The application uses Python 3.9 base image and:
1. Installs Python dependencies from `requirements.txt`
2. Installs system utilities (cron)
3. Copies application code
4. Sets up entrypoint script for initialization
5. Exposes port 8000
### Entrypoint Process
The `entrypoint.sh` script:
1. Waits for PostgreSQL to be ready
2. Runs database migrations
3. Starts cron for scheduled tasks
4. Starts Django development server
5. Executes django-cron jobs every 12 hours
## Verification Steps
### 1. Check Running Containers
```bash
docker-compose ps
```
Expected output:
```
NAME COMMAND STATUS PORTS
luna_backend_web /entrypoint.sh Up 0.0.0.0:80->8000/tcp
luna_backend_db postgres Up 0.0.0.0:5432->5432/tcp
luna_backend_pgadmin pgadmin Up 0.0.0.0:8001->8001/tcp
```
### 2. Verify Database Connection
```bash
docker-compose exec web python manage.py dbshell
```
### 3. Check Migrations
```bash
docker-compose exec web python manage.py showmigrations
```
### 4. Access Admin Panel
Navigate to [http://localhost/admin](http://localhost/admin) and login with superuser credentials.
## Troubleshooting
### Port Conflicts
If ports 80, 5432, or 8001 are in use, modify `docker-compose.yml`:
```yaml
ports:
- "8080:8000" # Change web port
- "5433:5432" # Change database port
```
### Database Connection Issues
1. Ensure PostgreSQL container is running:
```bash
docker-compose ps db
```
2. Check environment variables in `.env`
3. Verify database logs:
```bash
docker-compose logs db
```
### Migration Errors
```bash
# Reset migrations (development only!)
docker-compose exec web python manage.py migrate --fake-initial
# Or manually delete migration files and recreate
docker-compose exec web python manage.py makemigrations
docker-compose exec web python manage.py migrate
```
### Permission Issues
```bash
# Fix container permissions
docker-compose exec web chmod +x /entrypoint.sh
```
## Next Steps
After successful installation:
1. **Configure Modules** - Create university modules via admin panel
2. **Add Users** - Register students and lecturers
3. **Create Surveys** - Design forms for data collection
4. **Review Architecture** - See [Architecture Guide](./architecture.md)
5. **Understand Workflows** - See [Student Experience](./student-experience.md) and [Lecturer Experience](./lecturer-experience.md)
## Production Deployment
For production deployment on AWS EC2 with Nginx:
1. Use production-ready database (RDS or managed PostgreSQL)
2. Configure Nginx as reverse proxy
3. Set `DEBUG=False` in environment
4. Use proper SSL certificates
5. Configure allowed hosts
6. Set up database backups
7. Implement monitoring and logging
***
**Support**: For issues, consult project documentation or contact the development team.
# Lecturer View
Source: https://methodscenter.mintlify.app/web-platform/lecturer-view
## Lecturer Features & Use Cases
### 1. Account Management
#### Create Lecturer Account
* Register with university email
* Set user\_type to LECTURER (2)
* Associate with university
* Receive lecturer permissions
#### Access Admin Interface
* Login to Django admin panel at `/admin`
* Manage modules and settings
* View system-wide data
* Configure platform features
***
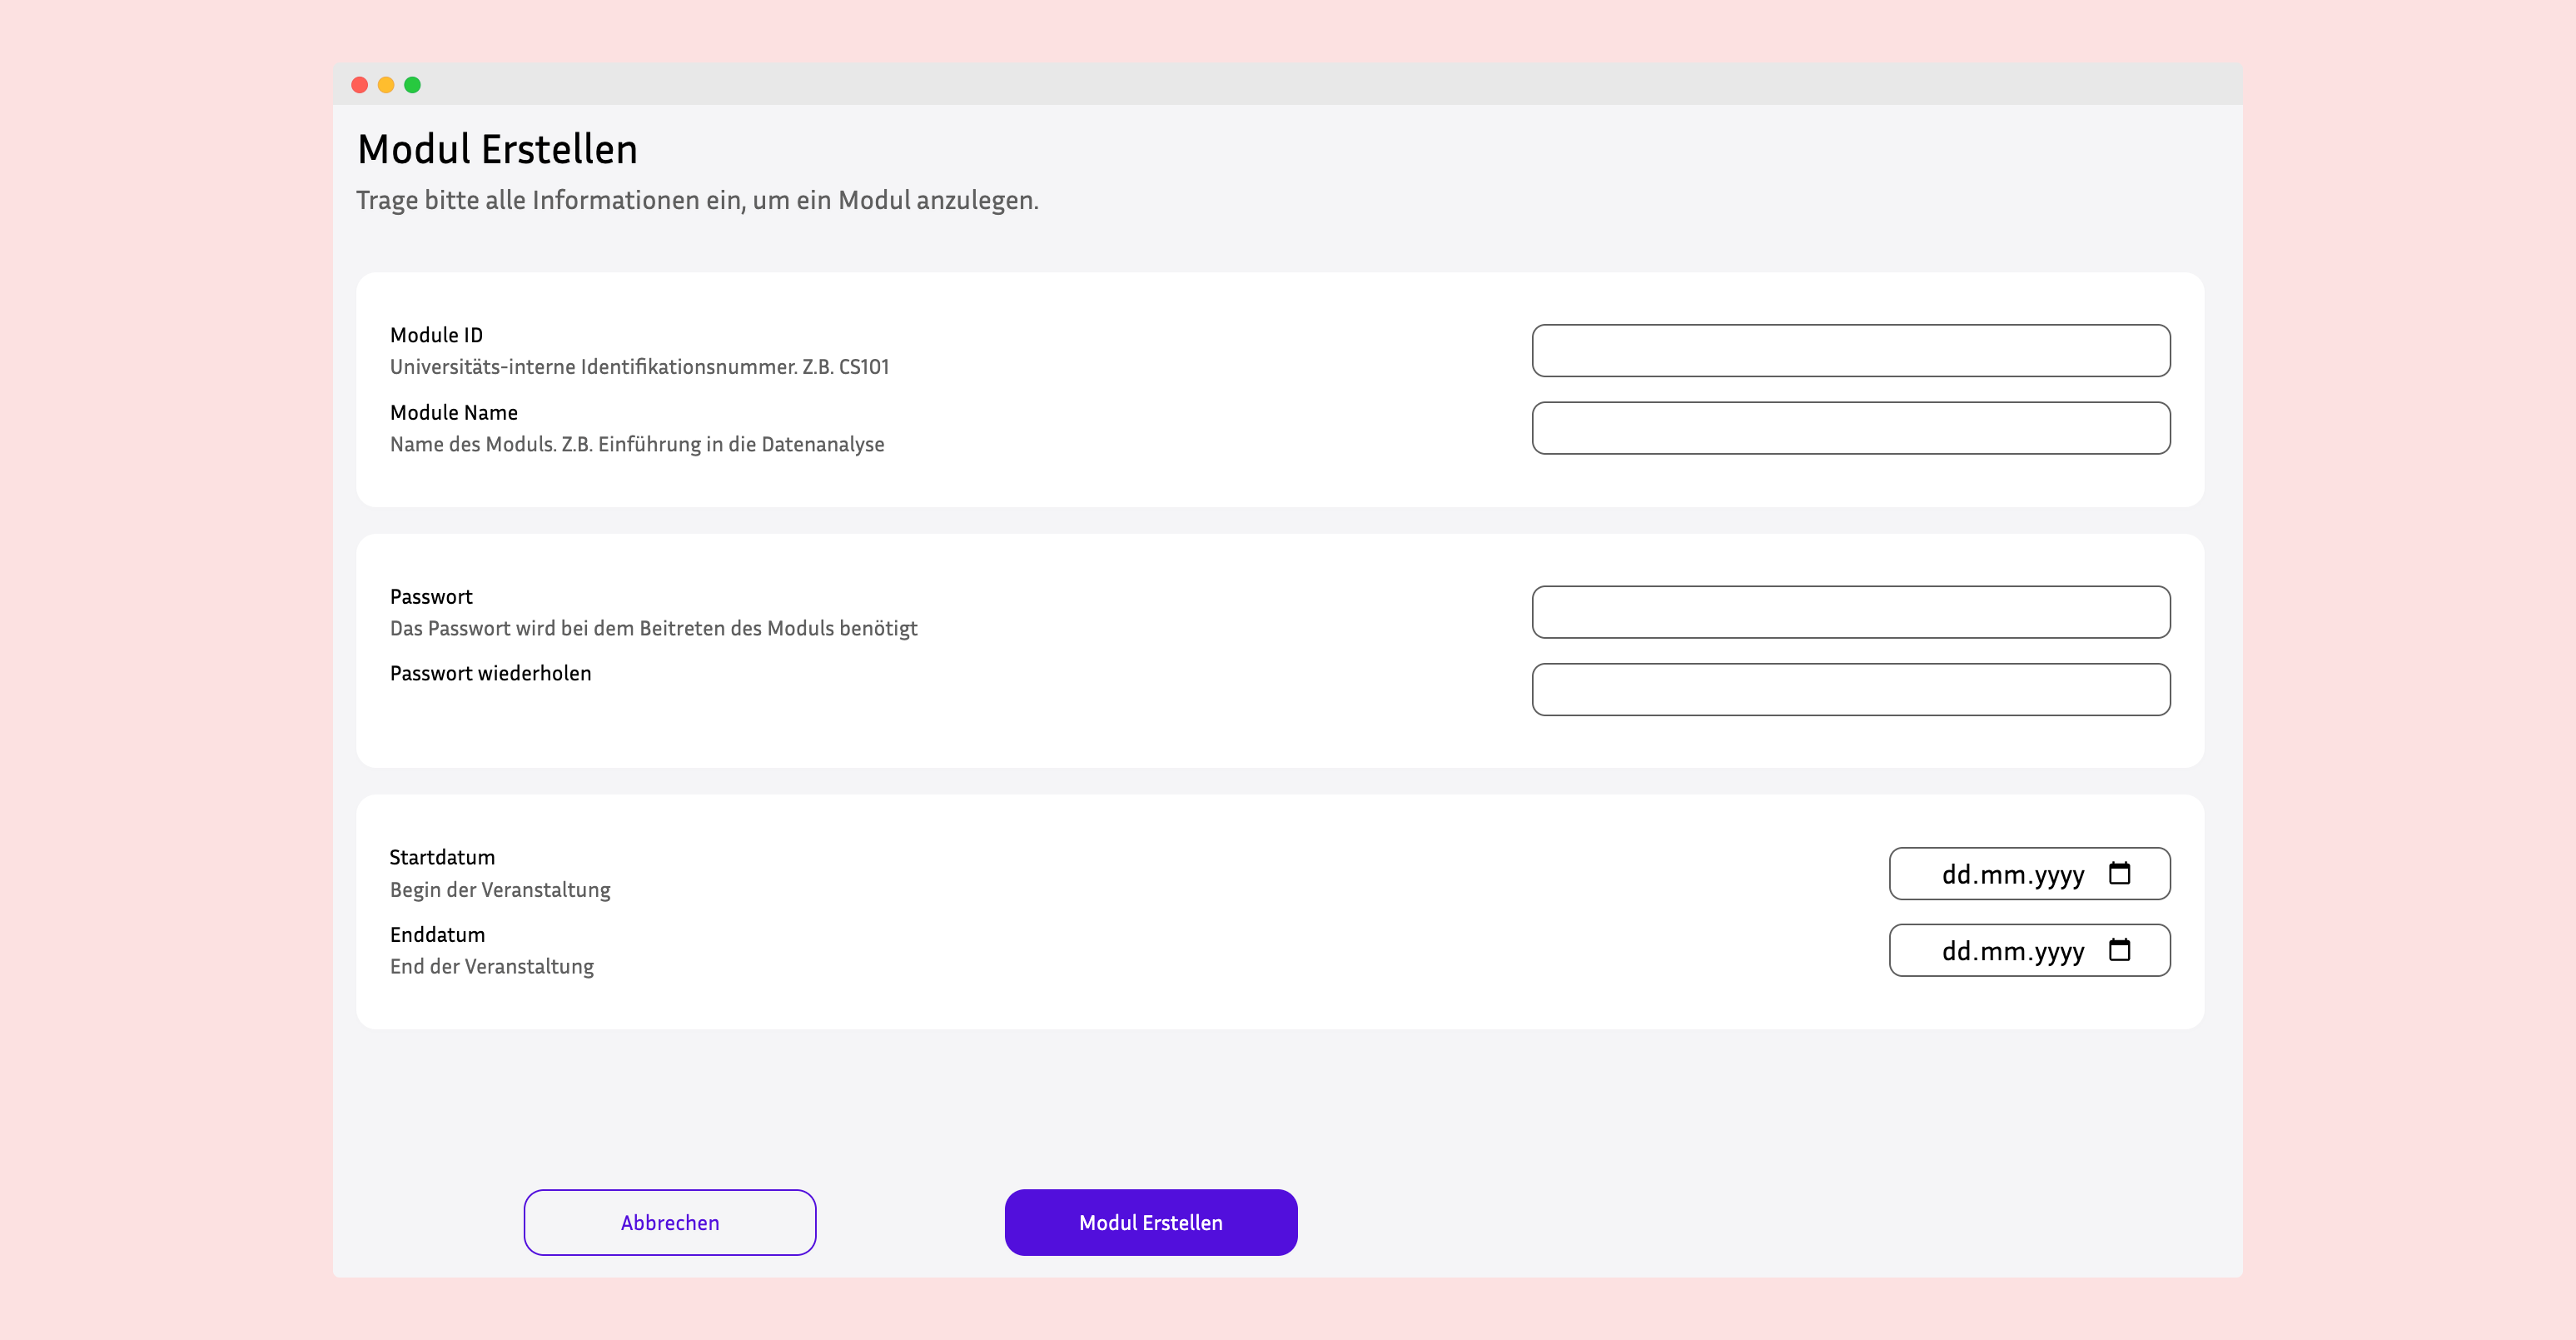
### 2. Module Management
#### Create New Module
* Define module details:
* Module name (e.g., "Mathematics I")
* Module code (e.g., "MATH101")
* Semester (Winter/Summer)
* Start and end dates
* Survey days (select days of week: Monday, Wednesday, etc.)
* Module password for student enrollment
* Set module status (Active/Inactive)
* Assign to university
 #### Configure Module Settings
* Set survey schedule days (e.g., Mondays and Thursdays)
* Define semester period
* Create secure enrollment password
* Update module status
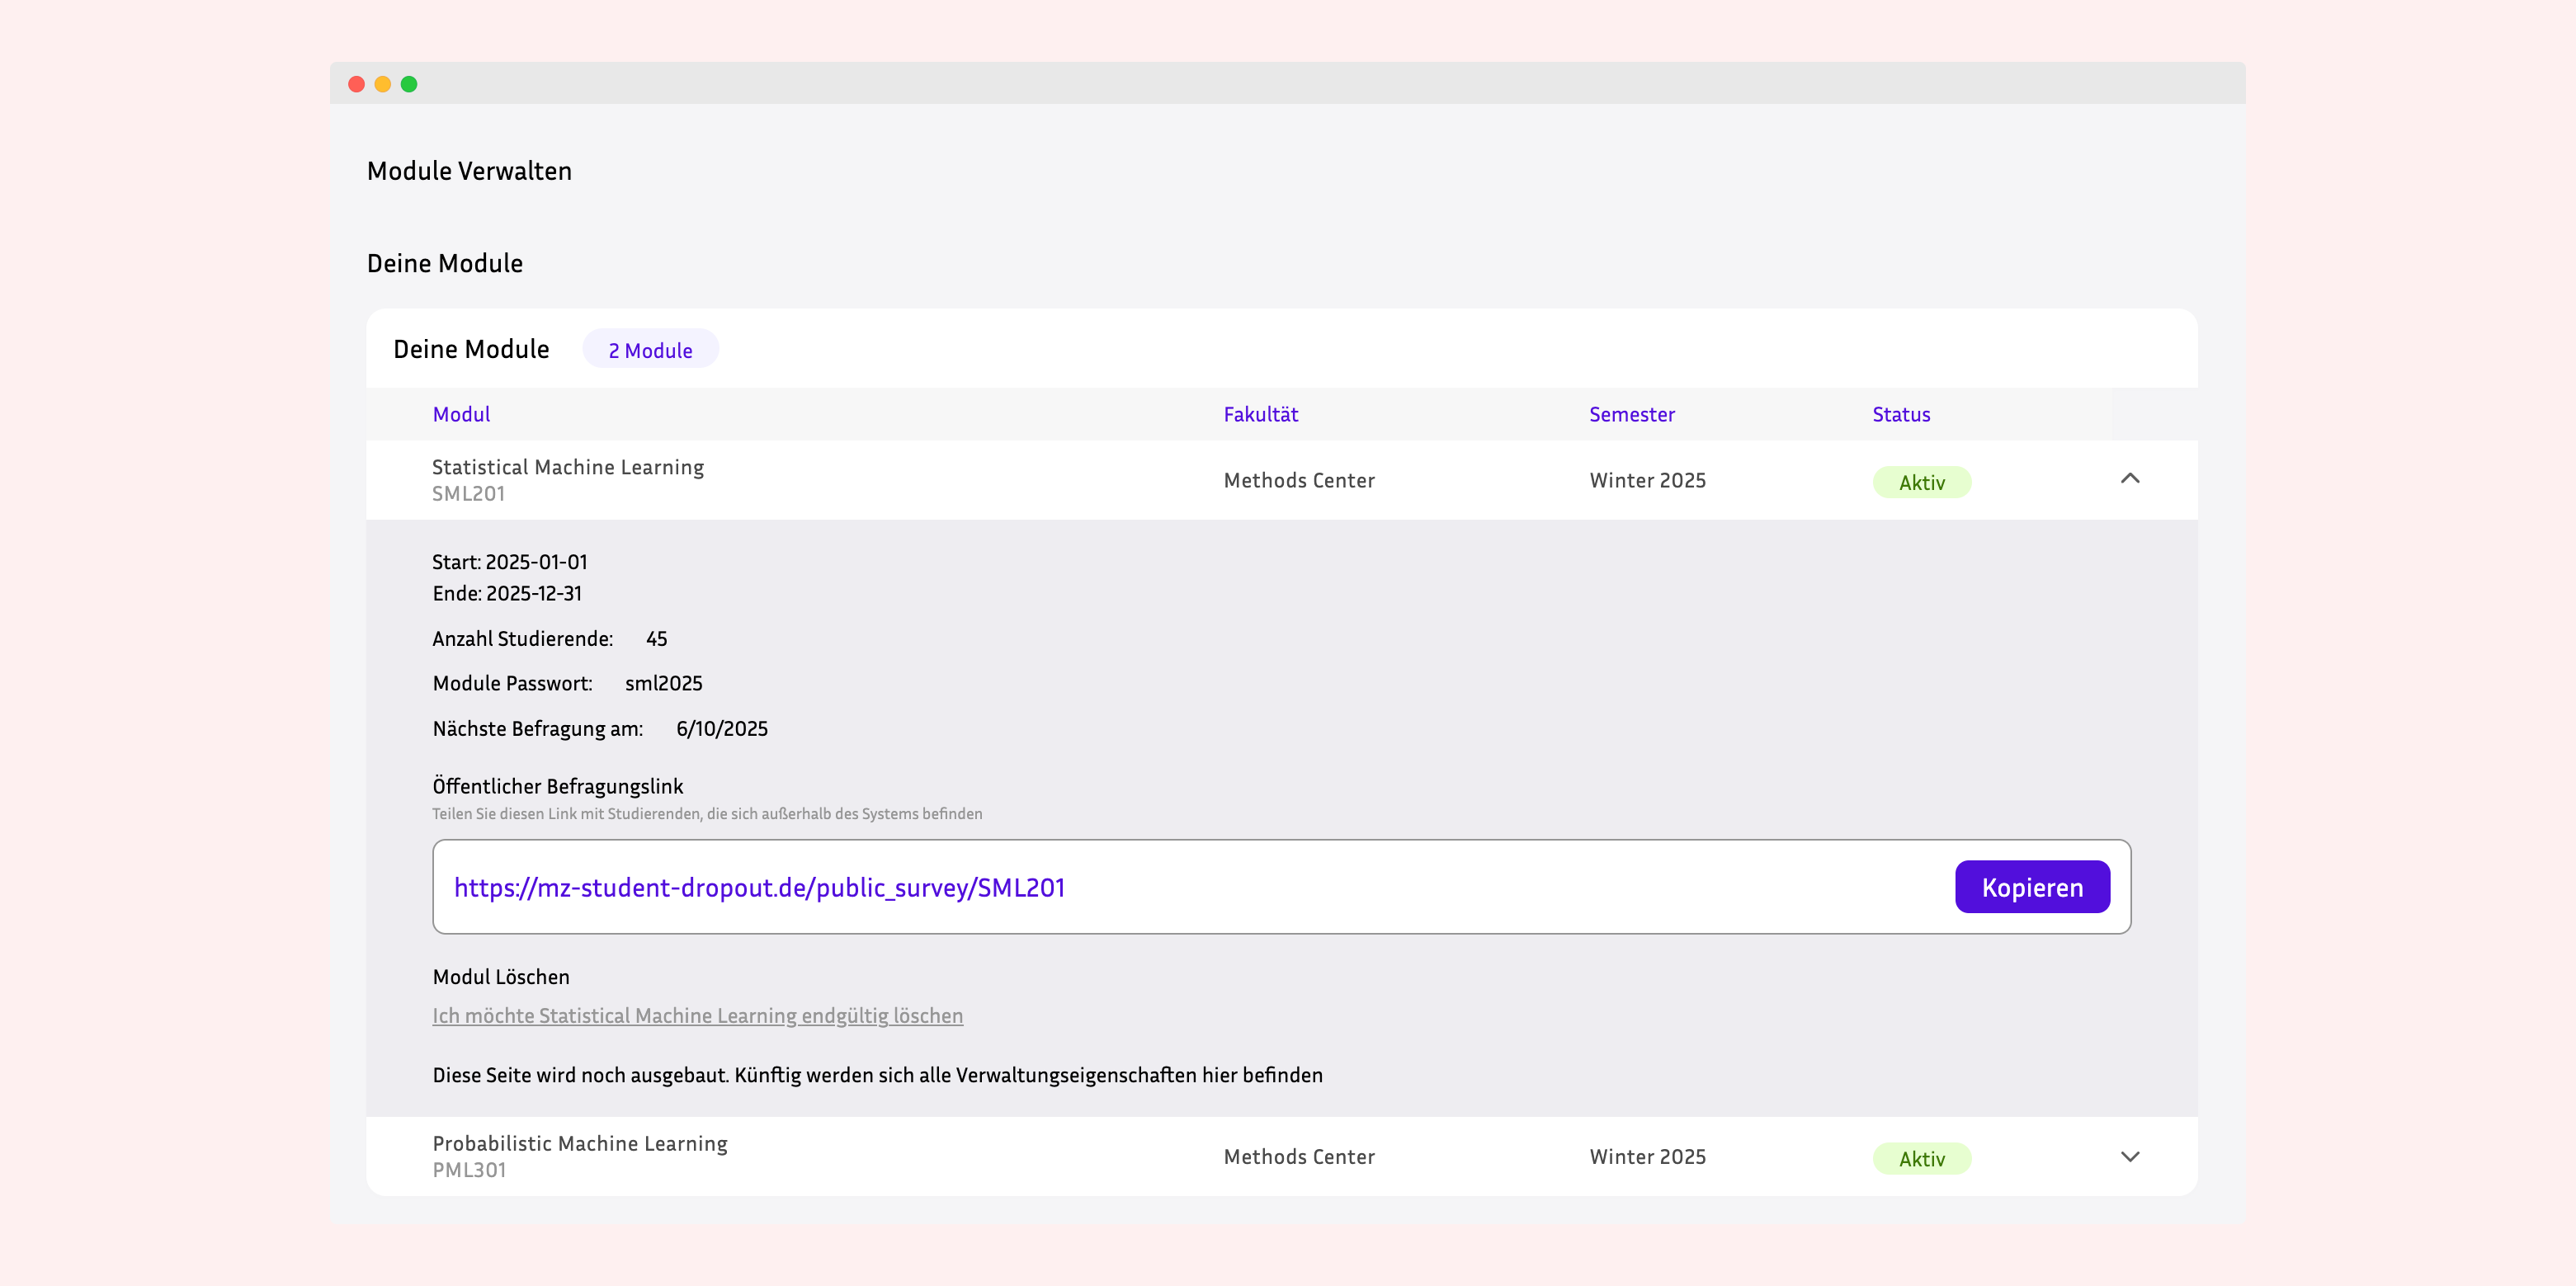
#### Manage Module Access
* Share module password with enrolled students
* Control module activation/deactivation
* Update module information
* Archive completed modules
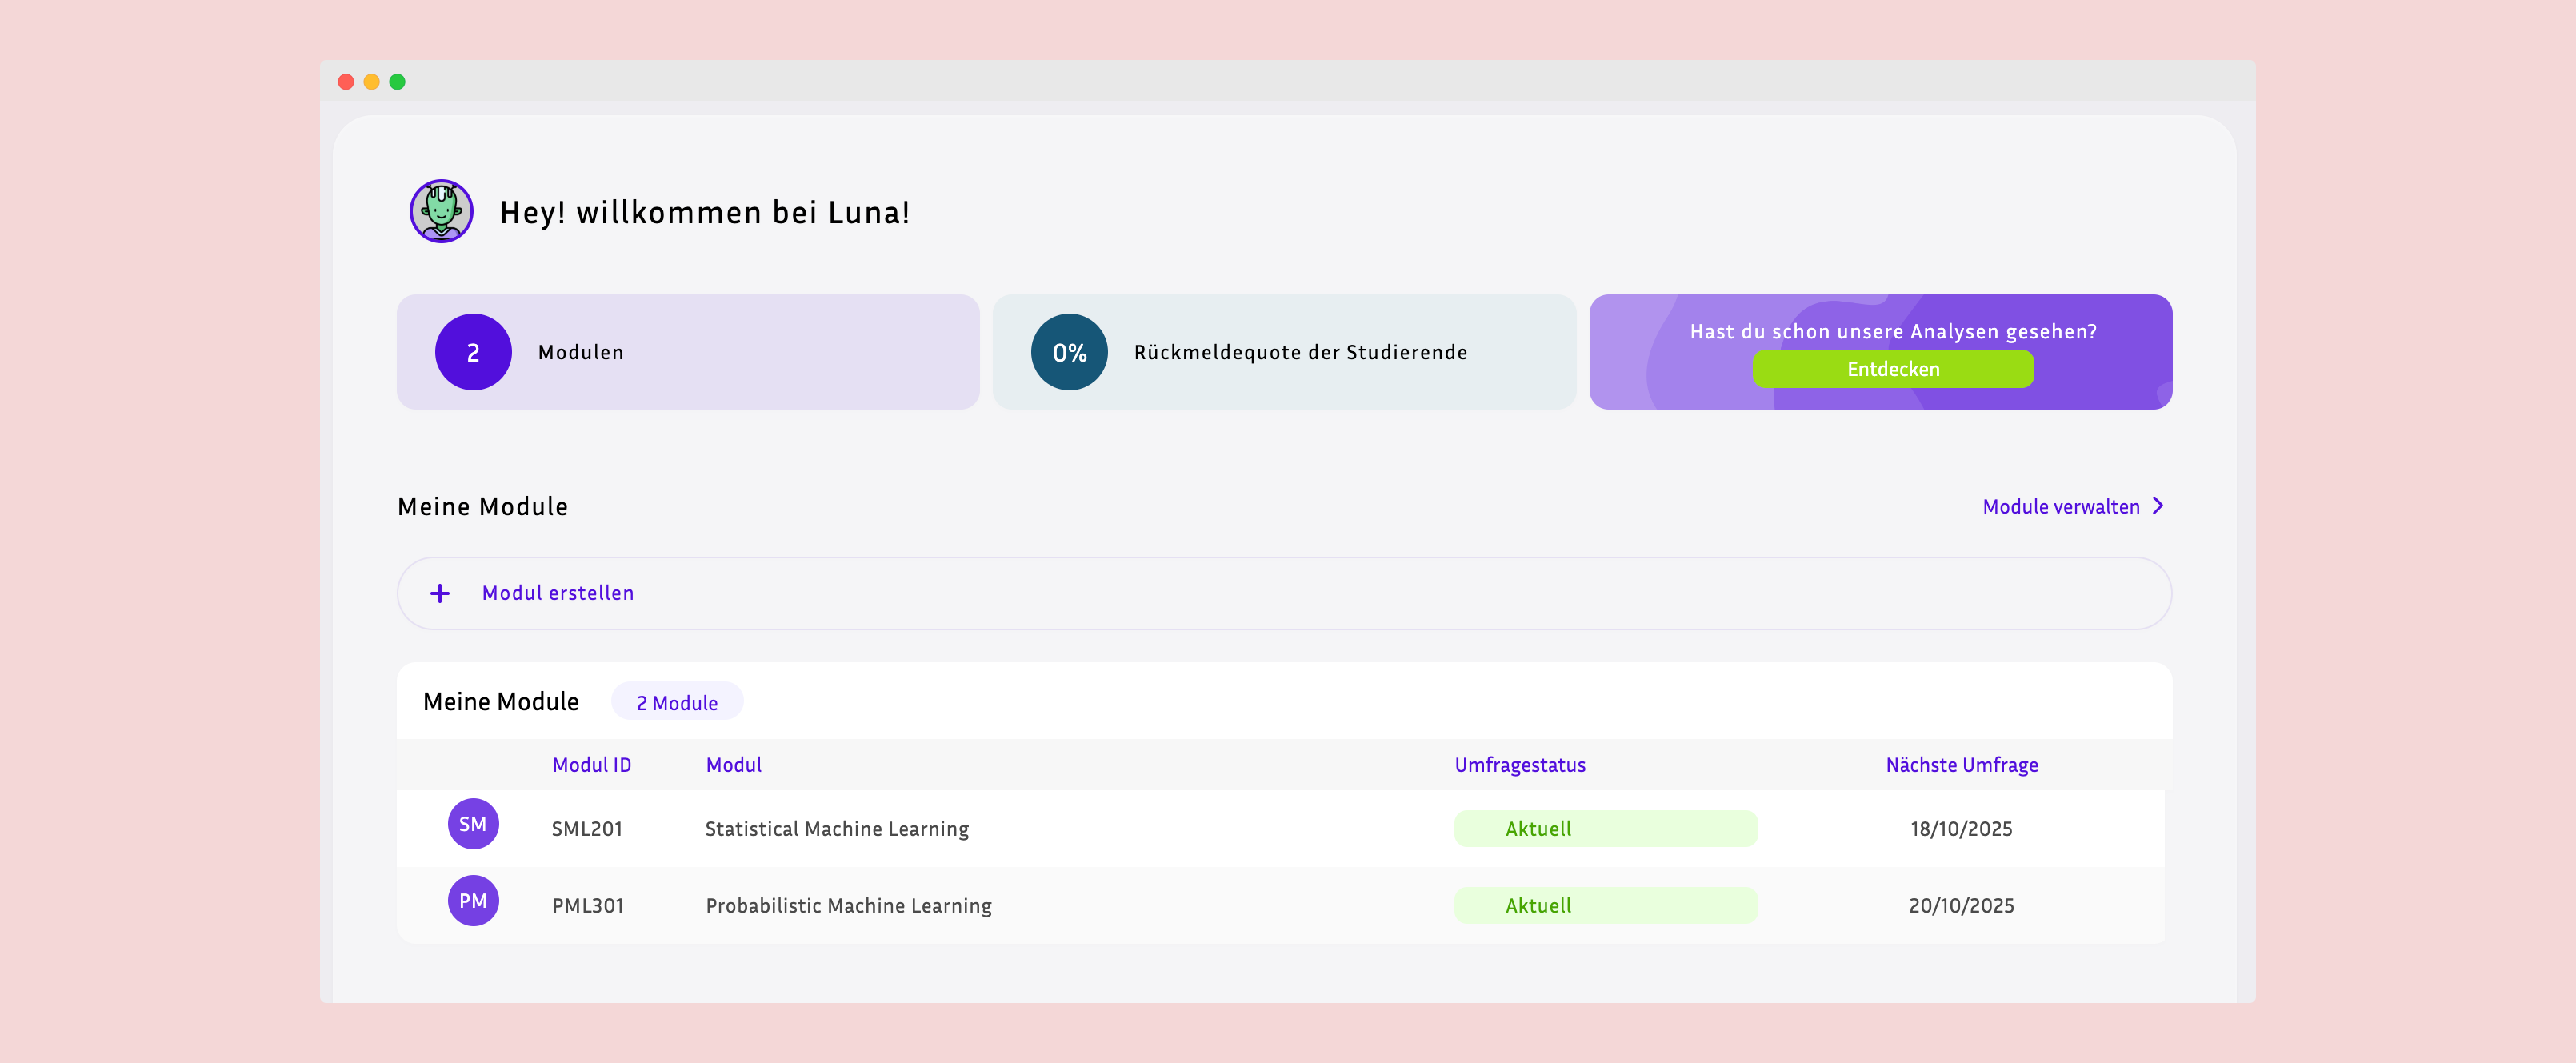
#### View Module Statistics
* See total enrolled students
* Monitor enrollment trends
* Track student participation
* View module activity
 ***
### 3. Survey & Form Management
#### Create Survey Forms
* Design custom forms using JSON structure
* Define question types and formats
* Set form metadata (name, description)
* Configure form deployment settings
 #### Deploy Surveys
* Surveys auto-deploy on configured survey days
* System automatically creates StudentSurvey instances
* All enrolled students receive surveys simultaneously
* Cron job handles scheduled deployment
#### Monitor Survey Responses
* View survey completion rates
* Track submission timestamps
* See individual student responses
* Monitor resolution status (Completed/Not Completed)
#### Manage Survey Content
* Update survey questions
* Modify form structure (JSON)
* Create multiple survey versions
* Archive old surveys
***
### 4. Student Management
#### View Enrolled Students
* Access list of all students in module
* See student profile information:
* Name and email
* Student ID
* Enrollment date
* Demographic data (if permitted)
#### Track Student Participation
* Monitor survey completion per student
* View participation rates
* Identify at-risk students (low participation)
* Track longitudinal engagement
#### Manage Enrollments
* Approve/reject enrollments (if manual approval enabled)
* Remove students from module
* View enrollment history
* Export student lists
***
### 5. Data Collection & Analysis
#### Access Survey Data
* View all survey responses for module
* Export data in various formats
* Access raw JSON response data
* Download datasets for analysis
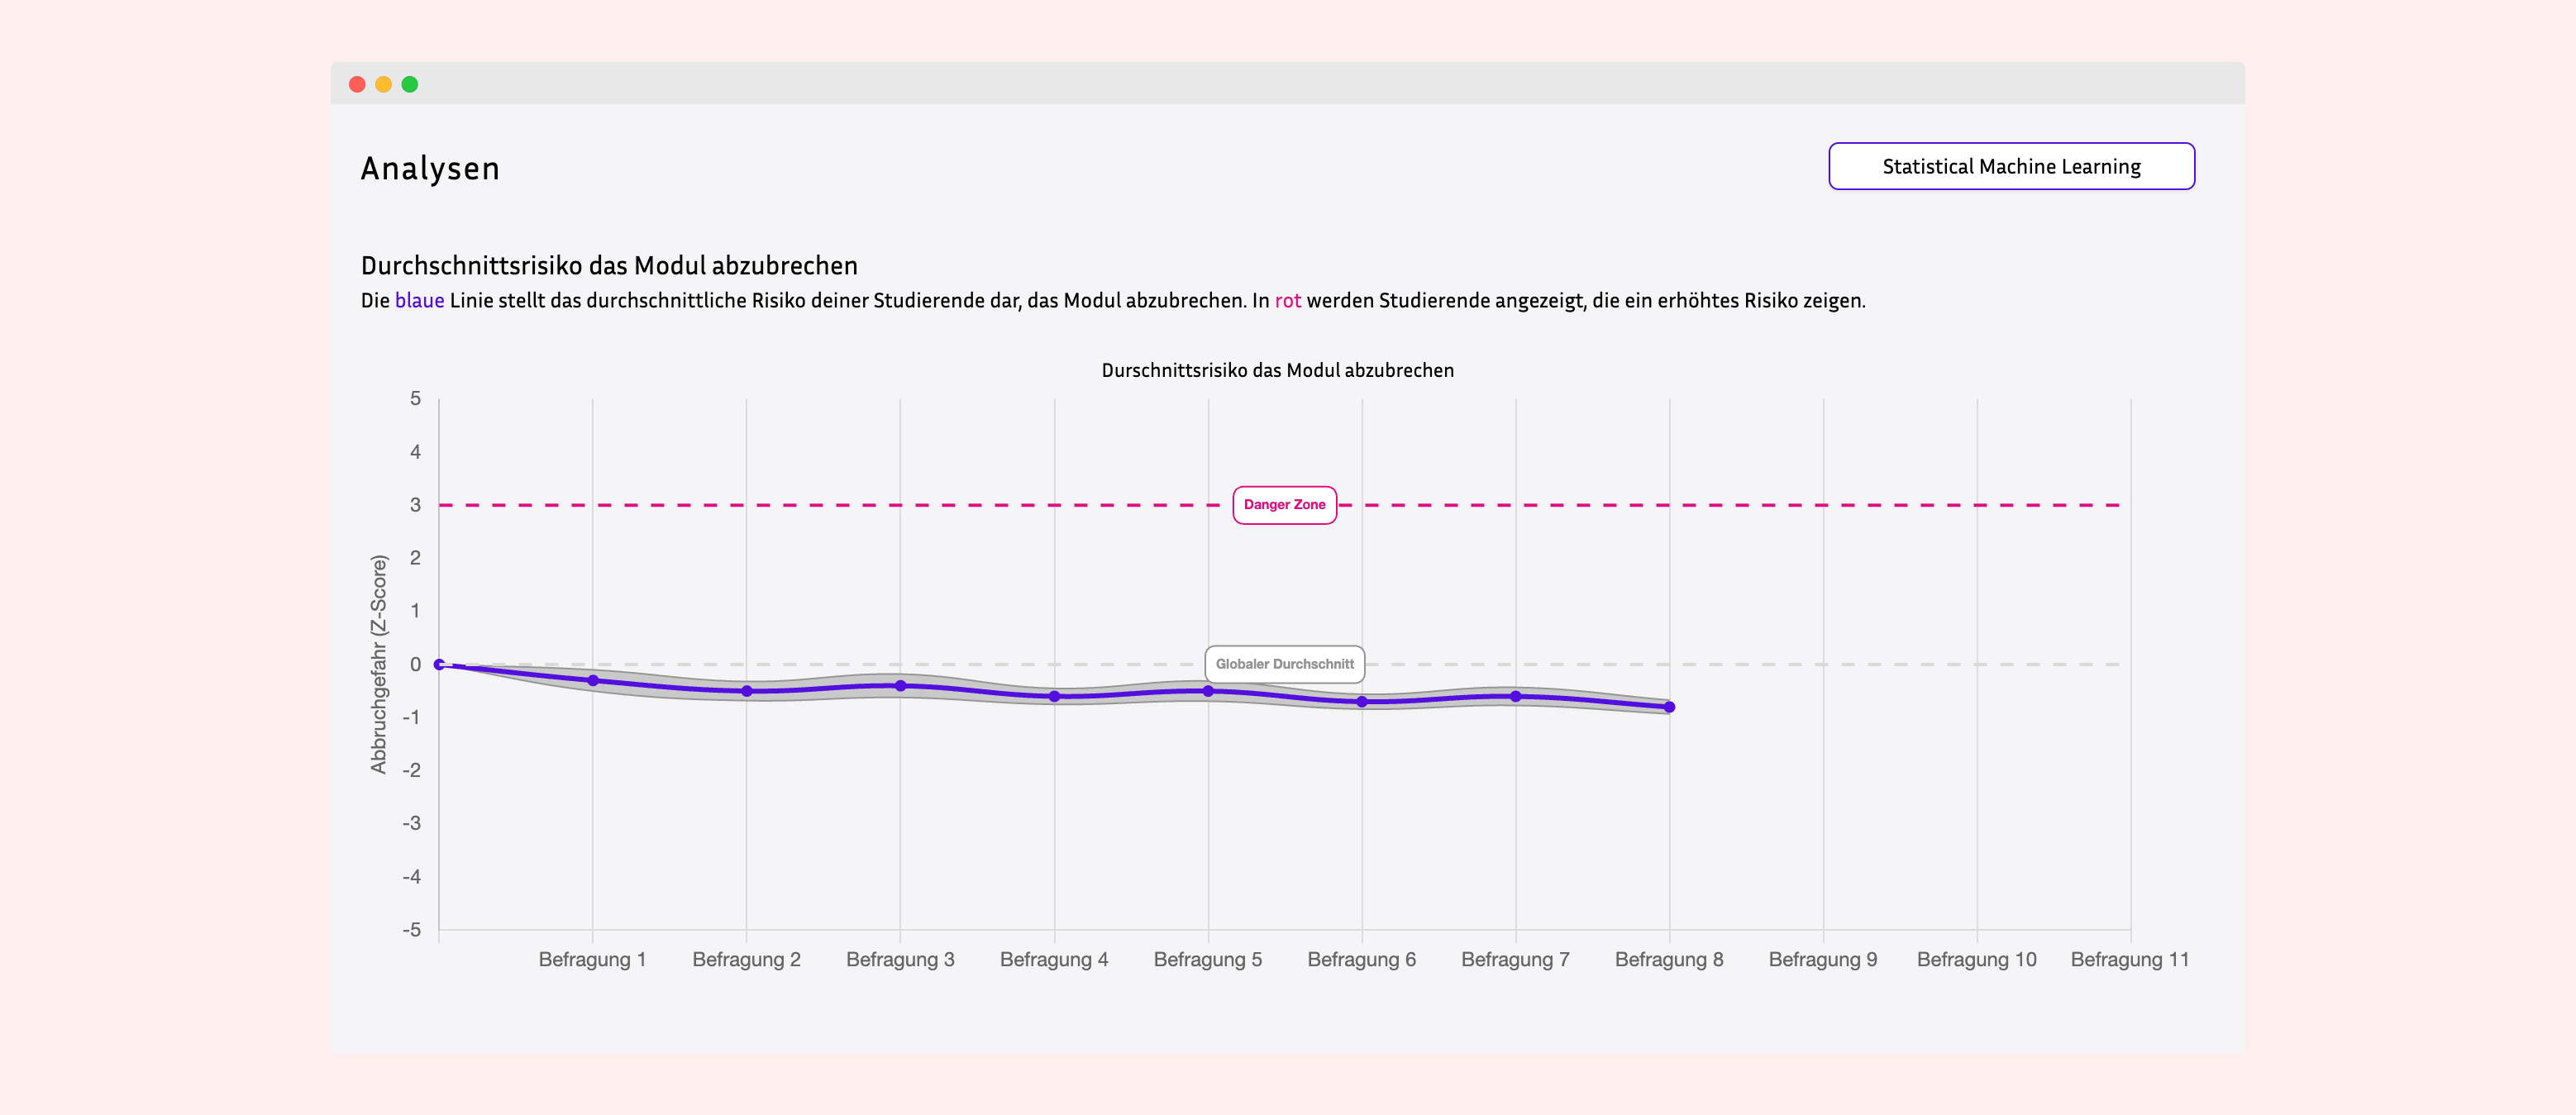
#### Generate Reports
* Survey completion statistics
* Student participation metrics
* Time-series response data
* Module performance indicators
 #### Export Data for Research
* Extract structured datasets
* Export to CSV, JSON formats
* Prepare data for statistical analysis
* Support psychometric modeling
***
### 6. Administrative Functions
#### Module Lifecycle Management
* Create module at semester start
* Activate for student enrollment
* Monitor throughout semester
* Deactivate at semester end
* Archive for historical records
#### System Configuration
* Configure survey automation settings
* Manage cron job schedules
* Set notification preferences
* Update module parameters
***
## Lecturer User Workflows
### Typical Semester Setup Workflow
```
1. Create New Module
↓
2. Configure Module Settings
- Set dates (start/end)
- Select survey days
- Create enrollment password
↓
3. Design Survey Forms
- Create JSON form structure
- Define questions
↓
4. Activate Module (Status: ACTIVE)
↓
5. Share Password with Students
↓
6. Students Enroll
↓
7. Monitor Enrollments
↓
8. Cron Job Deploys Surveys Automatically
↓
9. Track Student Participation
↓
10. Collect & Analyze Data
↓
11. End Semester - Deactivate Module
```
### Weekly Monitoring Routine
```
Survey Day (e.g., Monday)
↓
Cron Job Creates StudentSurvey Instances
↓
Lecturer Logs into Admin Panel
↓
Navigate to Module Dashboard
↓
Check Survey Deployment Status
↓
Monitor Student Completion Rates
↓
Identify Non-Responders
↓
Send Reminders (if needed)
↓
Review Submitted Responses
↓
Export Data for Analysis
```
***
## Use Case Examples
### Use Case 1: Setting Up New Mathematics Course
**Actor**: Mathematics Lecturer
**Steps**:
1. Login to admin panel
2. Navigate to "Modules" section
3. Click "Add Module"
4. Enter details:
* Name: "Linear Algebra I"
* Code: "MATH210"
* University: "University of Tübingen"
* Semester: "Winter Semester"
* Start: October 15, 2024
* End: February 28, 2025
* Survey Days: Monday, Thursday
* Password: "LinAlg2024!"
5. Set Status: "Active"
6. Save module
**Outcome**: Module created and ready for student enrollment
***
### Use Case 2: Creating Custom Survey
**Actor**: Research-focused Lecturer
**Steps**:
1. Navigate to "Forms" in admin panel
2. Click "Add Form"
3. Enter form name: "Weekly Affective State Assessment"
4. Design JSON structure:
```json
{
"questions": [
{"id": 1, "type": "scale", "text": "Rate your stress level (1-10)"},
{"id": 2, "type": "scale", "text": "Rate your confidence in material (1-10)"},
{"id": 3, "type": "text", "text": "What challenges did you face this week?"},
{"id": 4, "type": "multiple", "text": "Study hours this week", "options": ["0-5", "6-10", "11-15", "16+"]}
]
}
```
5. Save form
6. Associate with module
**Outcome**: Custom survey ready for deployment
***
### Use Case 3: Monitoring Student Participation
**Actor**: Lecturer mid-semester
**Steps**:
1. Login to admin panel
2. Navigate to module "Mathematics I"
3. View "StudentSurvey" section
4. Filter by current week
5. See statistics:
* Total enrolled: 45 students
* Surveys deployed: 45
* Completed: 38 (84%)
* Not completed: 7 (16%)
6. Identify non-responders
7. Export list of students with low participation
**Outcome**: Actionable insights for student intervention
***
### Use Case 4: Exporting Research Data
**Actor**: Researcher/Lecturer
**Steps**:
1. Navigate to "StudentSurvey" in admin
2. Apply filters:
* Module: "Mathematics I"
* Date range: Oct 2024 - Feb 2025
* Resolution: Completed
3. Select all completed surveys
4. Click "Export selected to CSV"
5. Download dataset with:
* Student IDs (anonymized if needed)
* Survey numbers
* Timestamps
* JSON response content
6. Import to statistical software (R, Python, SPSS)
**Outcome**: Clean dataset ready for psychometric analysis
***
### Use Case 5: Managing Module Enrollment
**Actor**: Lecturer at semester start
**Steps**:
1. Create module with password "Math2024"
2. Announce in first lecture:
* "Enroll via Luna platform"
* "Module code: MATH101"
* "Password: Math2024"
3. Monitor enrollments daily
4. View enrolled student list
5. Cross-reference with official course roster
6. Identify students not yet enrolled
7. Send reminder emails
**Outcome**: All students enrolled and ready for data collection
***
### Use Case 6: Analyzing Longitudinal Trends
**Actor**: Research Lecturer
**Steps**:
1. Access module "Statistics I"
2. View survey history for student cohort
3. Track survey numbers 1-15 (across semester)
4. Export time-series data
5. Analyze patterns:
* Stress levels over time
* Confidence trends
* Correlation with exam periods
6. Identify at-risk students (declining engagement)
7. Plan intervention strategies
**Outcome**: Data-driven insights for student support
***
## Lecturer Capabilities Summary
### What Lecturers Can Do:
✅ **Module Management**
* Create and configure modules
* Set survey schedules
* Manage module lifecycle
* Control access with passwords
✅ **Survey Administration**
* Design custom forms (JSON)
* Deploy surveys automatically
* Monitor response rates
* Track completion status
✅ **Student Oversight**
* View enrolled students
* Track participation metrics
* Identify non-responders
* Monitor engagement trends
✅ **Data Management**
* Access survey responses
* Export datasets
* Generate reports
* Prepare research data
✅ **Admin Access**
* Use Django admin panel
* Configure system settings
* Manage users (limited)
* View analytics
✅ **Research Functions**
* Collect longitudinal data
* Export for statistical analysis
* Support psychometric modeling
* Generate insights
### What Lecturers Cannot Do:
❌ Access student data from other lecturers' modules
❌ Modify system-wide settings (admin only)
❌ Delete submitted student responses (data integrity)
❌ Create universities or faculties (admin only)
❌ Access superuser functions
❌ Modify other lecturers' modules
***
## Lecturer Interface Components
### Key Admin Panel Sections:
1. **Dashboard** - Overview of owned modules
2. **Modules Management** - CRUD operations for modules
3. **Forms/Surveys** - Create and manage survey instruments
4. **StudentSurvey** - View and export response data
5. **StudentModule** - Monitor enrollments
6. **Users** - View student profiles (limited)
7. **Reports** - Analytics and statistics
### Module Detail View Components:
* **Module Information** - Name, code, dates, status
* **Enrolled Students** - List with participation stats
* **Survey Schedule** - Configured survey days
* **Response Tracking** - Completion rates and trends
* **Data Export** - Download options
***
## Automated Features for Lecturers
### Survey Auto-Deployment
* **Cron Job**: Runs every 12 hours
* **Logic**: Checks current day against module survey\_days
* **Action**: Creates StudentSurvey for enrolled students
* **Benefit**: No manual survey distribution needed
### Enrollment Management
* **Student Self-Enrollment**: Password-based system
* **Automatic Profile Creation**: StudentUser auto-created
* **Validation**: Unique student-module constraint
* **Benefit**: Reduced administrative overhead
### Data Integrity
* **Survey Numbering**: Auto-incremented per student-module
* **Timestamp Tracking**: Automatic creation and submission times
* **Status Management**: Resolution auto-updated on submission
* **Benefit**: Clean, structured datasets
***
## Best Practices for Lecturers
### Module Setup
1. Create module at least 1 week before semester start
2. Test survey deployment with sample students
3. Communicate password clearly to students
4. Set realistic survey days (not too frequent)
### Survey Design
1. Keep surveys concise (10-15 minutes max)
2. Use consistent question formats
3. Test JSON structure before deployment
4. Include clear instructions in form
### Data Collection
1. Monitor participation weekly
2. Send reminders for low responders
3. Export data regularly for backup
4. Document survey versions for reproducibility
### Student Communication
1. Explain research purpose clearly
2. Emphasize data privacy
3. Provide technical support
4. Acknowledge participation importance
***
## Benefits for Lecturers
### Research Benefits
* **Automated Data Collection** - Scheduled survey deployment
* **Longitudinal Datasets** - Time-series student data
* **Flexible Survey Design** - JSON-based customization
* **Export Capabilities** - Multiple data formats
### Administrative Benefits
* **Self-Service Enrollment** - Password-based system
* **Automated Tracking** - Participation monitoring
* **Centralized Management** - Single admin interface
* **Scalability** - Support multiple modules/cohorts
### Educational Benefits
* **Student Insights** - Understanding affective states
* **Early Warning** - Identify at-risk students
* **Intervention Support** - Data-driven decisions
* **Course Improvement** - Evidence-based refinements
***
For technical details, see [Architecture Guide](./architecture.md)
For installation, see [Installation Guide](./installation.md)
For student features, see [Student Experience](./student-experience.md)
# null
Source: https://methodscenter.mintlify.app/web-platform/overview
# Luna Web Platform Overview
## Mission & Scope
Luna is a research-driven web platform that partners with universities to understand and mitigate mathematics student dropout. It combines structured wellbeing data collection, real-time analytics, and actionable insights so that researchers, lecturers, and support staff can coordinate interventions before students disengage.
This document provides a high-level orientation to the platform for new collaborators, grant partners, and technical contributors.
## Stakeholders
| Role | Primary Goals | Luna Support |
| ---------------------- | --------------------------------------------------------------------- | ---------------------------------------------------------------------------------- |
| **Researchers** | Capture longitudinal wellbeing data and evaluate retention hypotheses | Automated survey pipeline, raw/processed data exports, reproducible modelling jobs |
| **Lecturers** | Monitor module health and respond to concerning trends | Cohort dashboards, risk alerts, module configuration tools |
| **Students** | Receive timely check-ins and track personal wellbeing trends | Weekly micro-surveys, personal analytics, privacy controls |
| **Platform Engineers** | Operate the infrastructure reliably and securely | Containerised services, observability hooks, automated cron scheduling |
## Value Proposition
* **Evidence-based retention insights** – captures both background and weekly longitudinal signals, then applies Kalman-filter smoothing to detect at-risk trajectories early.
* **University-ready operations** – supports multi-university, multi-module deployments with lecturer-controlled enrolment and compliance-friendly data segregation.
* **Explainable analytics** – exposes cohort-level trends and per-student narratives that are rooted in transparent psychometric models rather than black-box scoring.
* **Extensible architecture** – API-first Django backend, modular modelling package, and documented analytics outputs simplify further research integrations.
## Core Capability Areas
1. **Identity & Access Management** – custom user model with student, lecturer, and administrator roles, university scoping, and Django admin support.
2. **Module & Survey Lifecycle** – background forms, password-protected module enrolments, scheduled weekly surveys, and reminder cron jobs.
3. **Analytics Pipeline** – modelling app orchestrates Kalman filtering and risk scoring, persisting smoothed metrics for dashboards and exports.
4. **Notifications & Reporting** – automated cron runners execute survey creation and analytics updates; optional email hooks are available for interventions.
5. **Operations & Observability** – containerised deployment (Docker + docker-compose), PostgreSQL persistence, and PGAdmin for manual inspection.
## Platform Components
| Component | Description | Key Technologies |
| --------------------- | --------------------------------------------------------------------------------------------- | ------------------------------------------------- |
| **Backend API** | RESTful endpoints for account management, module orchestration, forms, surveys, and analytics | Django 4.2.x, Django REST Framework |
| **Modelling Service** | Processes survey streams, performs Kalman filtering, and stores smoothed trajectories | Python data stack, custom modelling package |
| **Task Scheduling** | Ensures surveys are generated, processed, and escalated on time | `django-cron`, custom cron runner loop |
| **Data Layer** | Source of truth for all user, module, form, and survey data | PostgreSQL 14, Django ORM |
| **Ops Tooling** | Local and production observability, DB management, deployment automation | Docker, Docker Compose, PGAdmin, Makefile helpers |
## Feedback Channels
* **GitHub Issues** – for bugs and feature requests (tag with `web-platform`).
* **Research Steering Group** – meets monthly to review analytics findings and prioritise new instrumentation.
* **Security & Compliance** – report incidents to the platform administrators; SOC-style runbooks are documented in the private operations repository.
> 📚 Continue with the companion guides:
>
> * `web-platform/installation.md` for developer setup instructions.
> * `web-platform/architecture.md` for infrastructure, data modelling, and request flows.
> * `web-platform/student-experience.md` and `web-platform/lecturer-experience.md` for persona-centred walkthroughs.
# Student View
Source: https://methodscenter.mintlify.app/web-platform/student-view
Show how students interact with the platform and what they gain from it.
## Student Features & Use Cases
### 1. Account Management
#### Create Account
* Register with email address, first name, and last name
* Receive email verification (if enabled)
* Set secure password
* Select affiliated university
#### Complete Student Profile
* Add personal information:
* Middle name and nickname
* Birth date
* Abitur grade (German university entrance qualification)
* Main language (English, German, Other)
* Financial support status
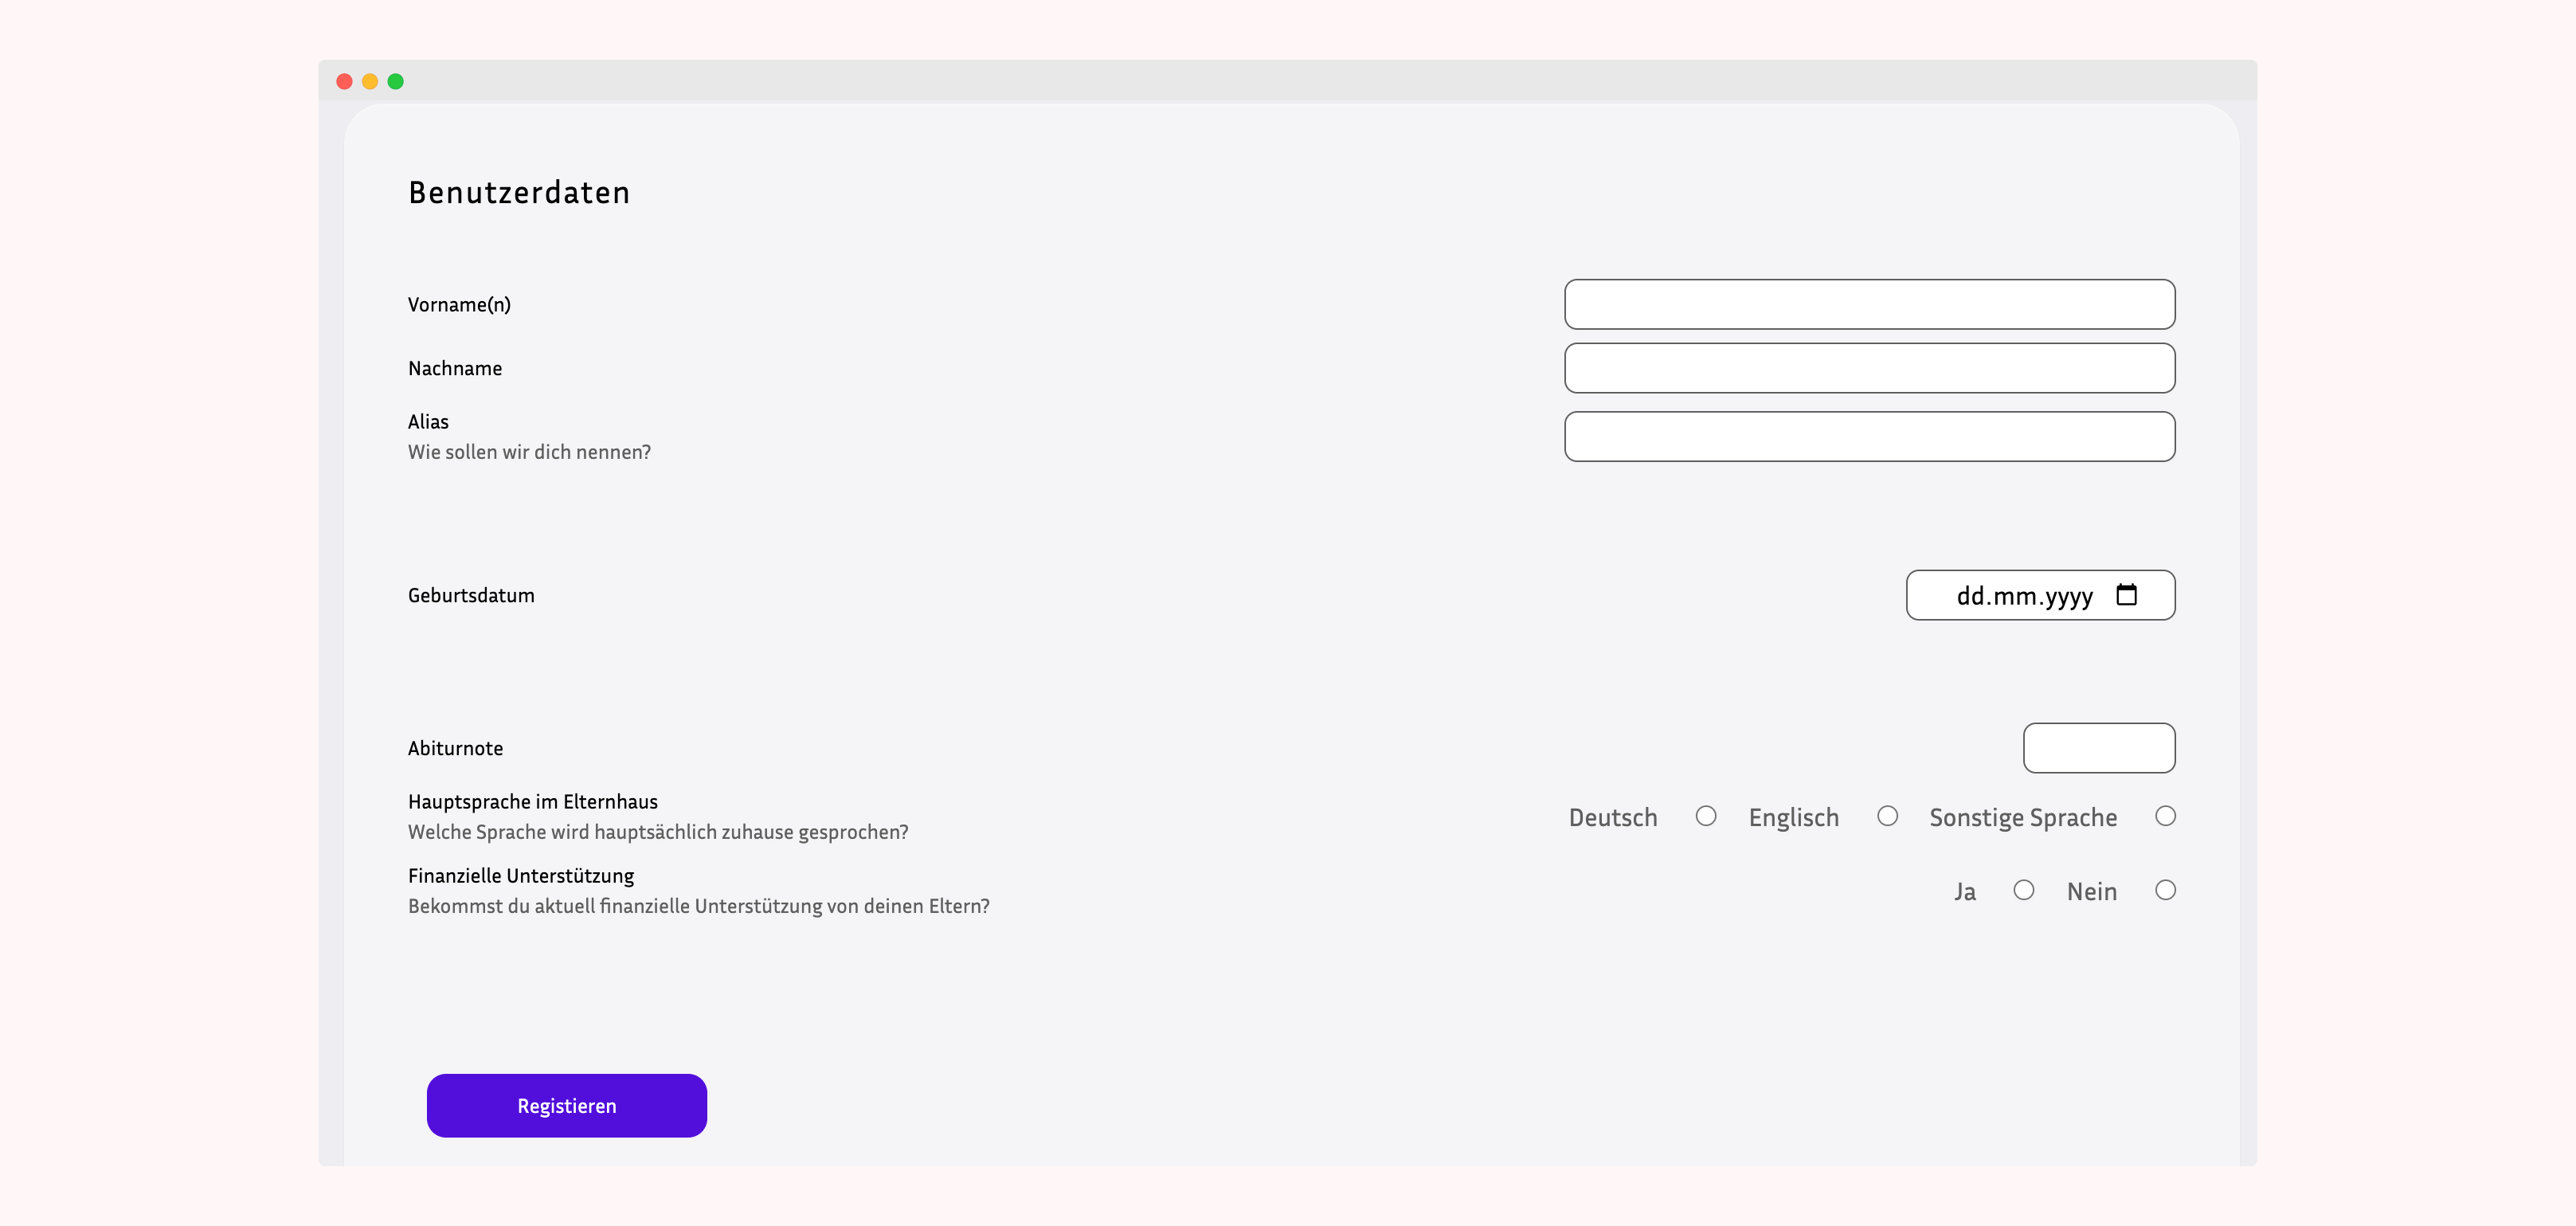 #### Complete Background Questionnaires
* Fill onboarding forms that capture educational history and support needs
* Provide context for personalised monitoring before module enrollment
* Navigate across the background and survey panels — both must be completed to finish onboarding
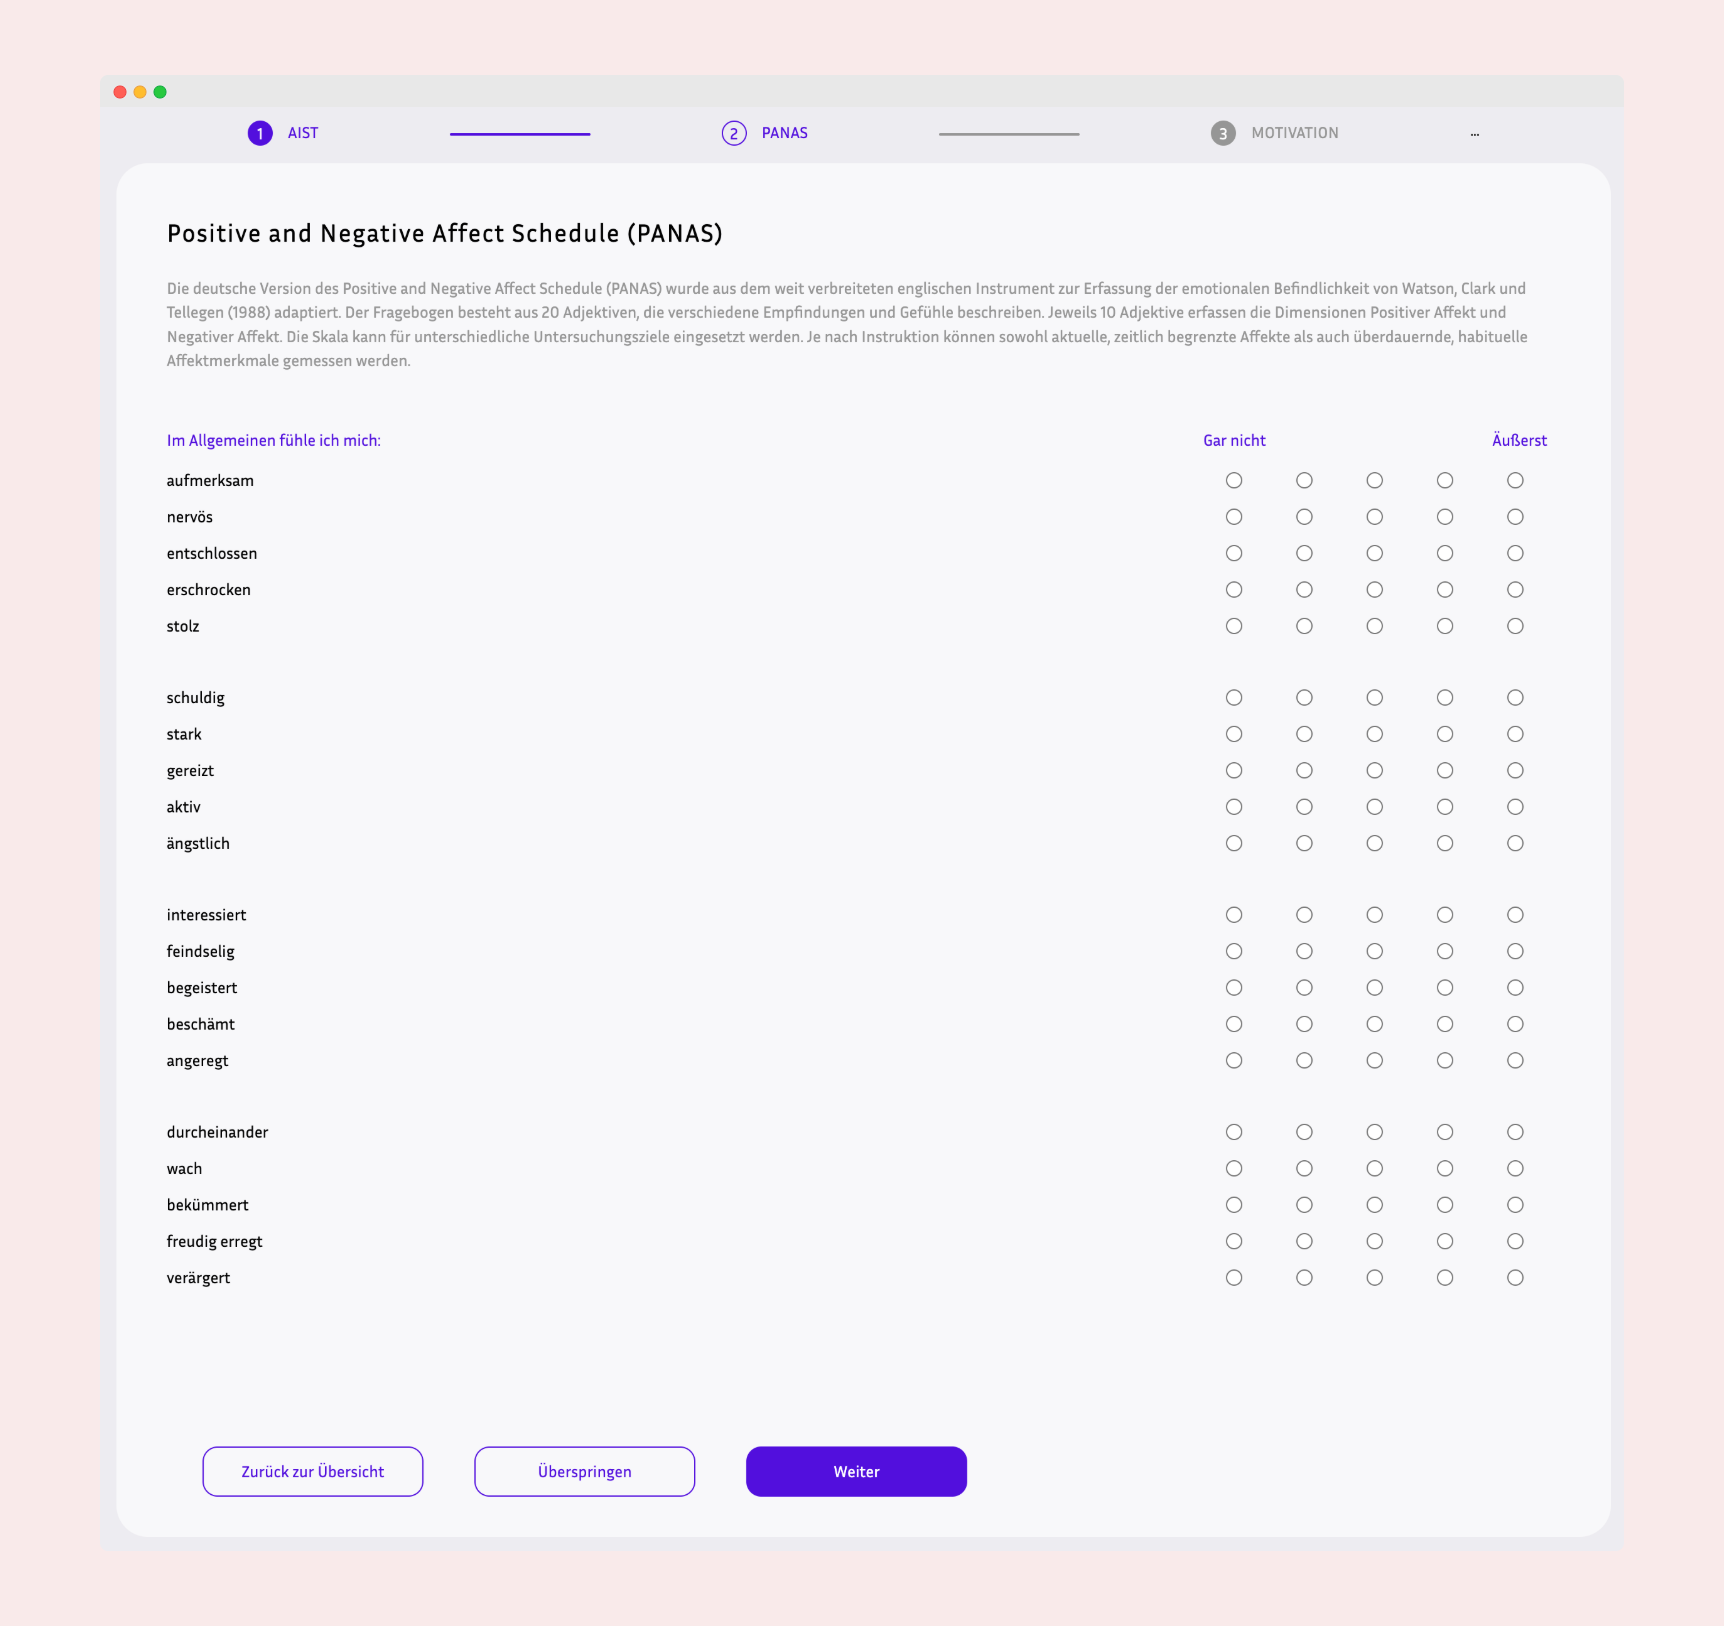 #### Manage Account Settings
* Update profile information
* Change password
* View account status
***
### 2. Module Enrollment
#### Browse Available Modules
* View list of active modules at your university
* See module details:
* Module name and code
* Semester (Winter/Summer)
* Start and end dates
* Lecturer/owner information
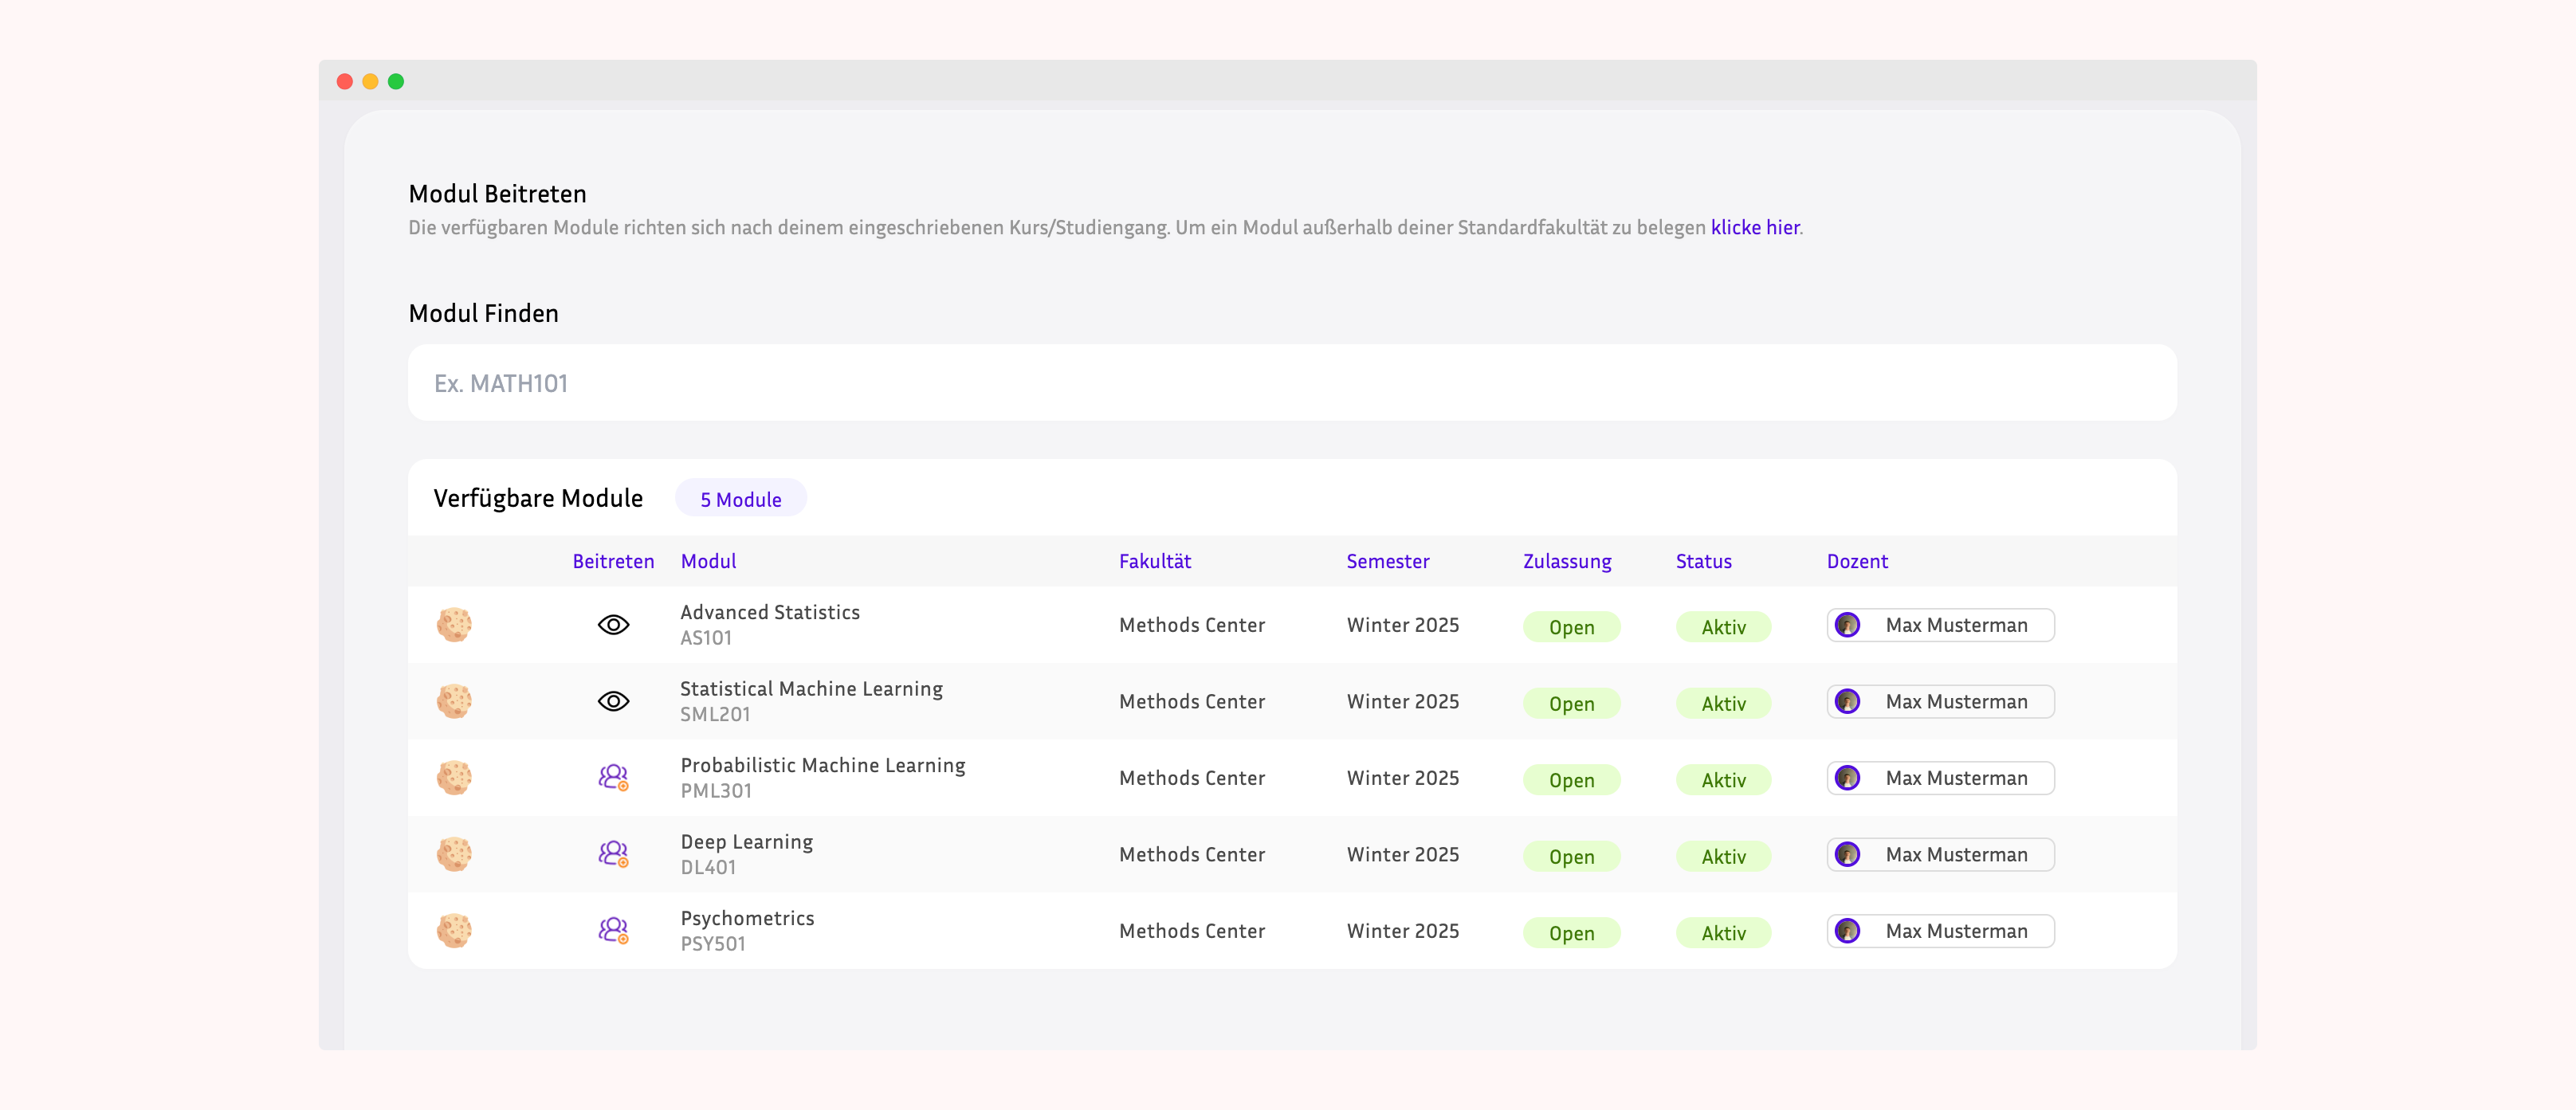 #### Enroll in Modules
* Enter module password provided by lecturer
* Receive enrollment confirmation
* Access enrolled module dashboard
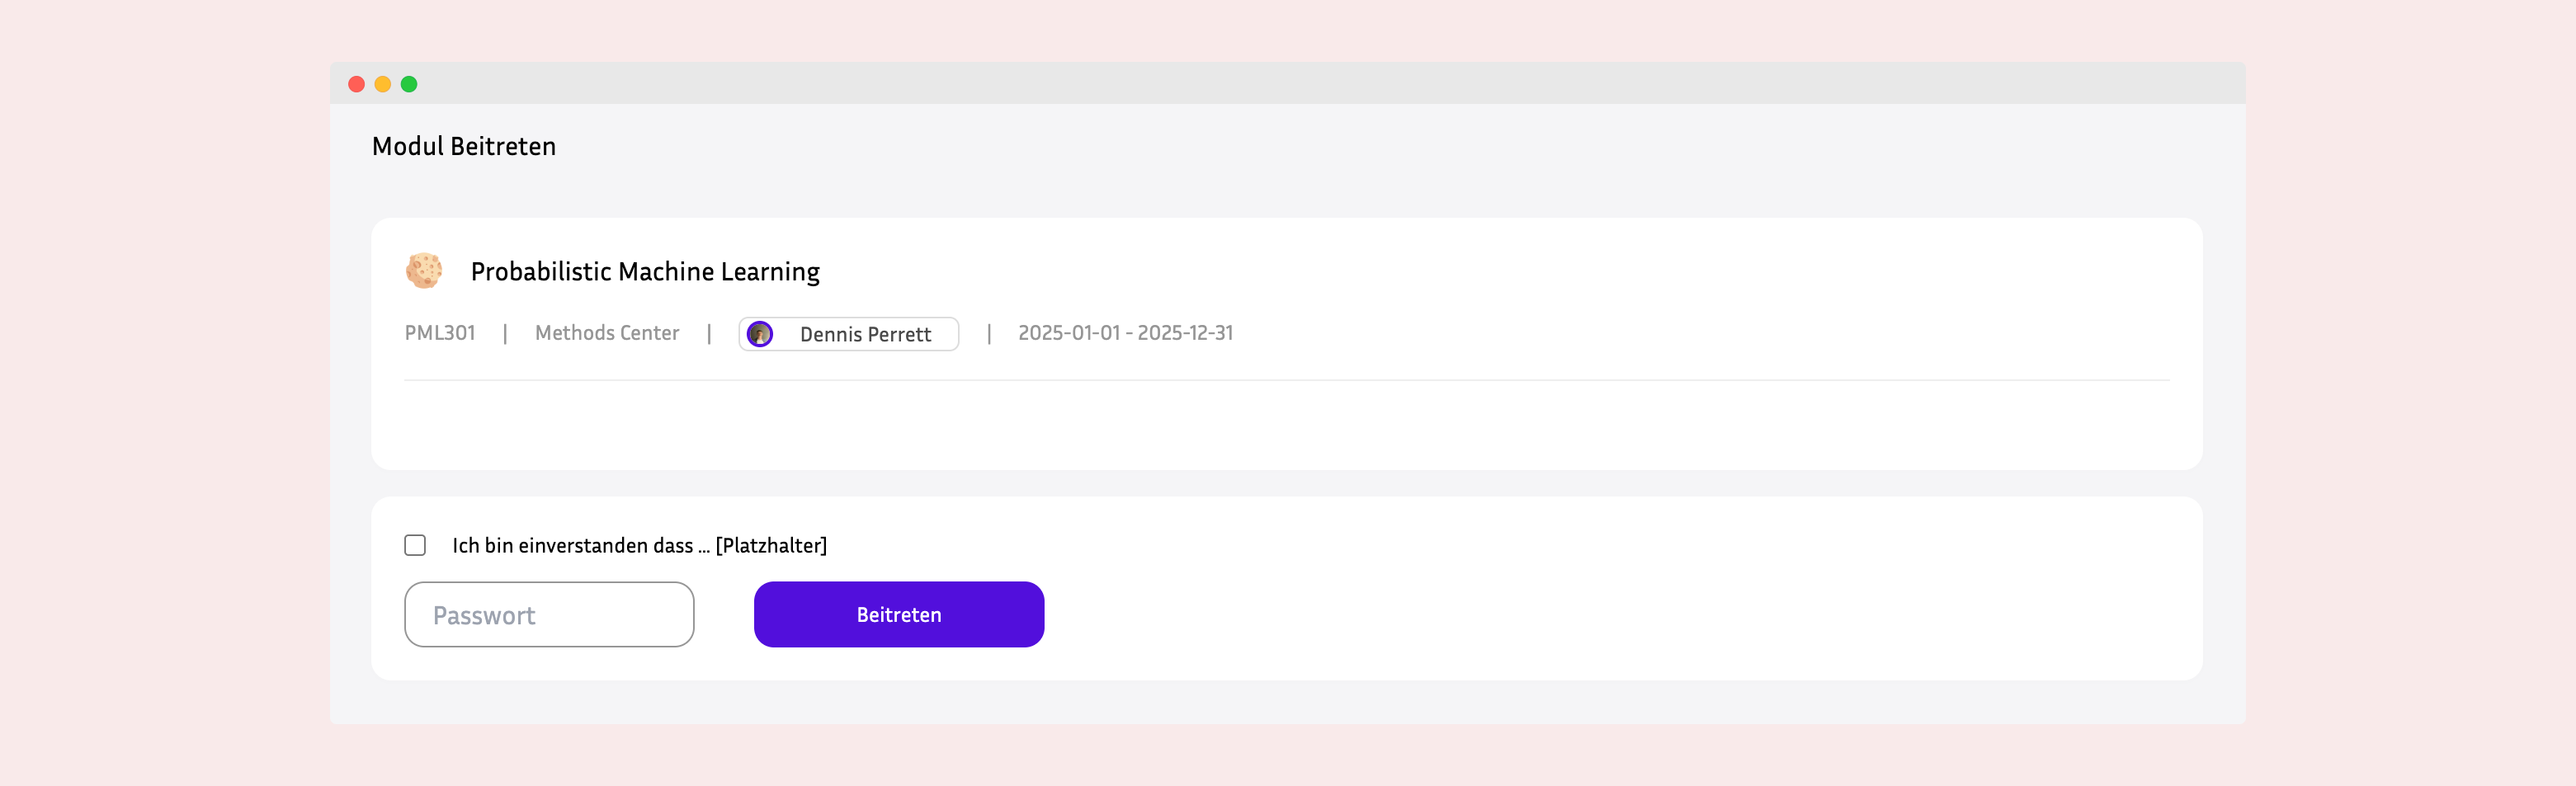 #### View Enrolled Modules
* See all currently enrolled modules
* Track enrollment status
* Access module-specific information
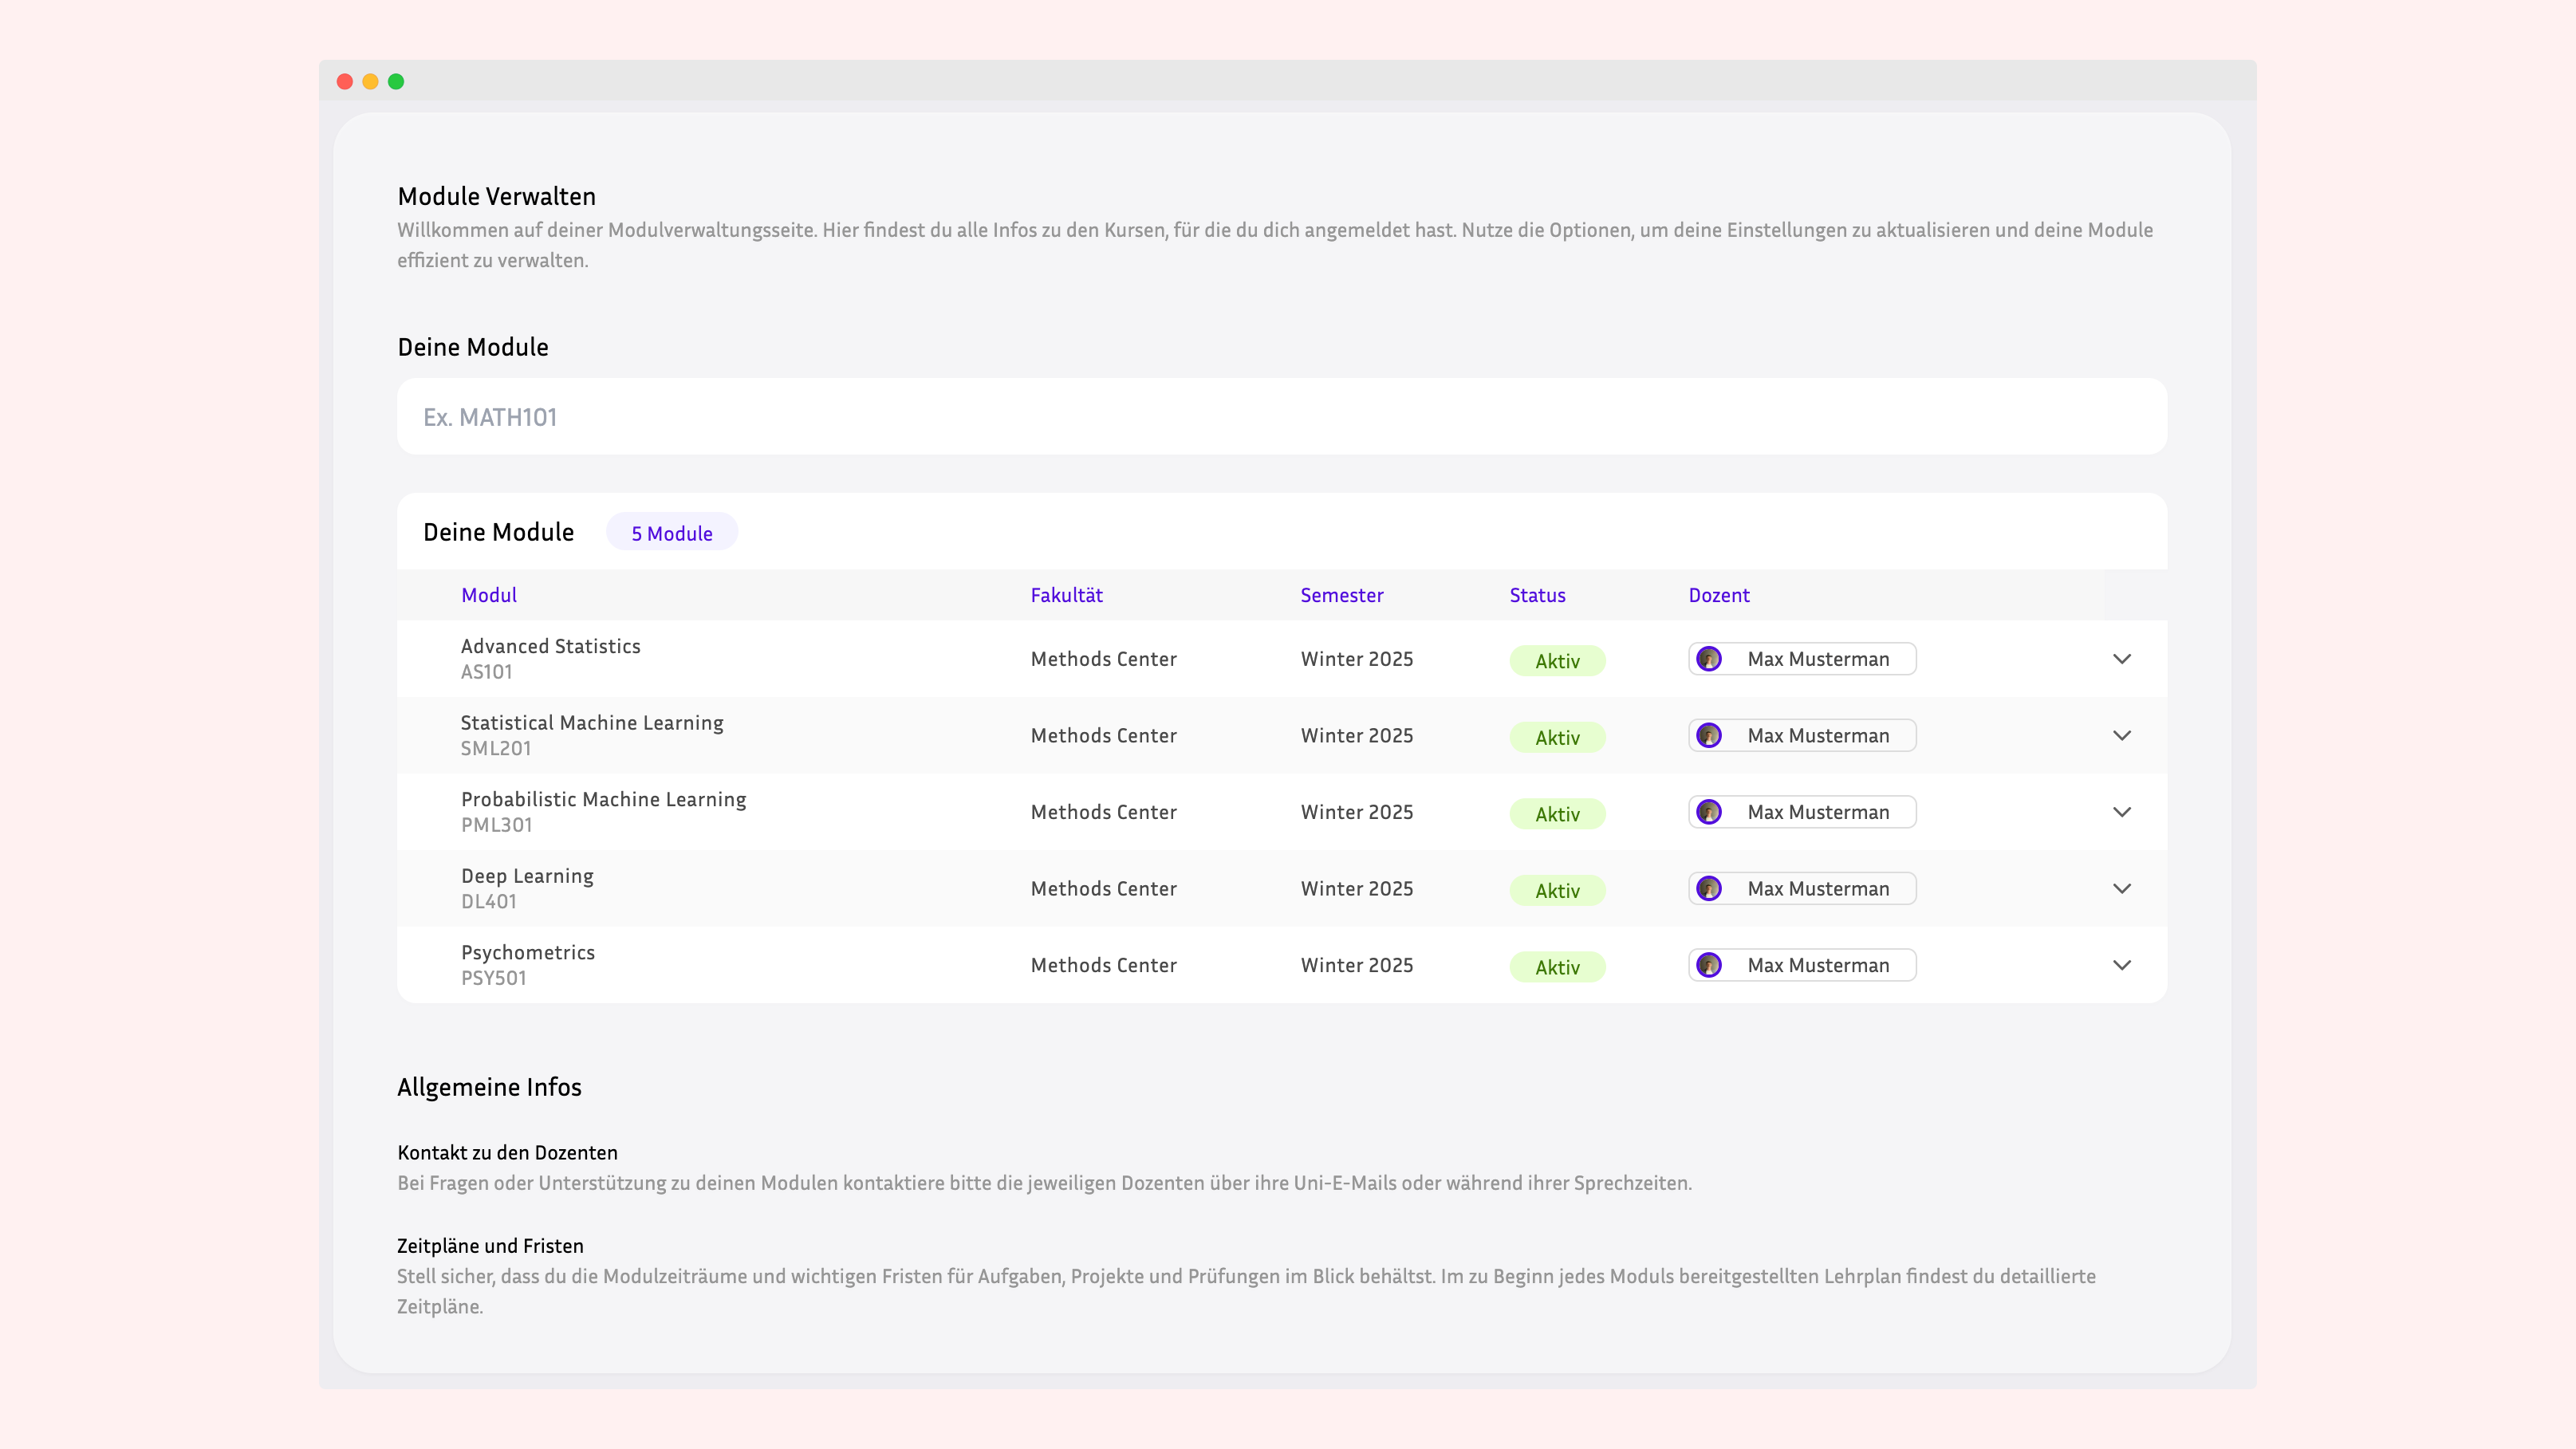 ***
### 3. Survey Participation
#### Receive Surveys
* Automatically receive surveys on scheduled survey days
* Get notifications for new pending surveys
* View survey deadlines and time windows
#### Fill Out Surveys
* Access survey forms from dashboard
* Answer questions (various types supported via JSON structure)
* Save progress (if enabled)
* Submit completed surveys
 #### Track Survey History
* View all past surveys
* See completion status (Completed/Not Completed)
* Review survey numbers and dates
* Access survey timeline per module
#### Manage Survey Status
* View pending surveys requiring completion
* Track submission timestamps
* Monitor survey resolution status
***
### 4. Data & Analytics
#### View Personal Analytics
* See survey completion rates
* Track participation statistics
* View progress over time per module
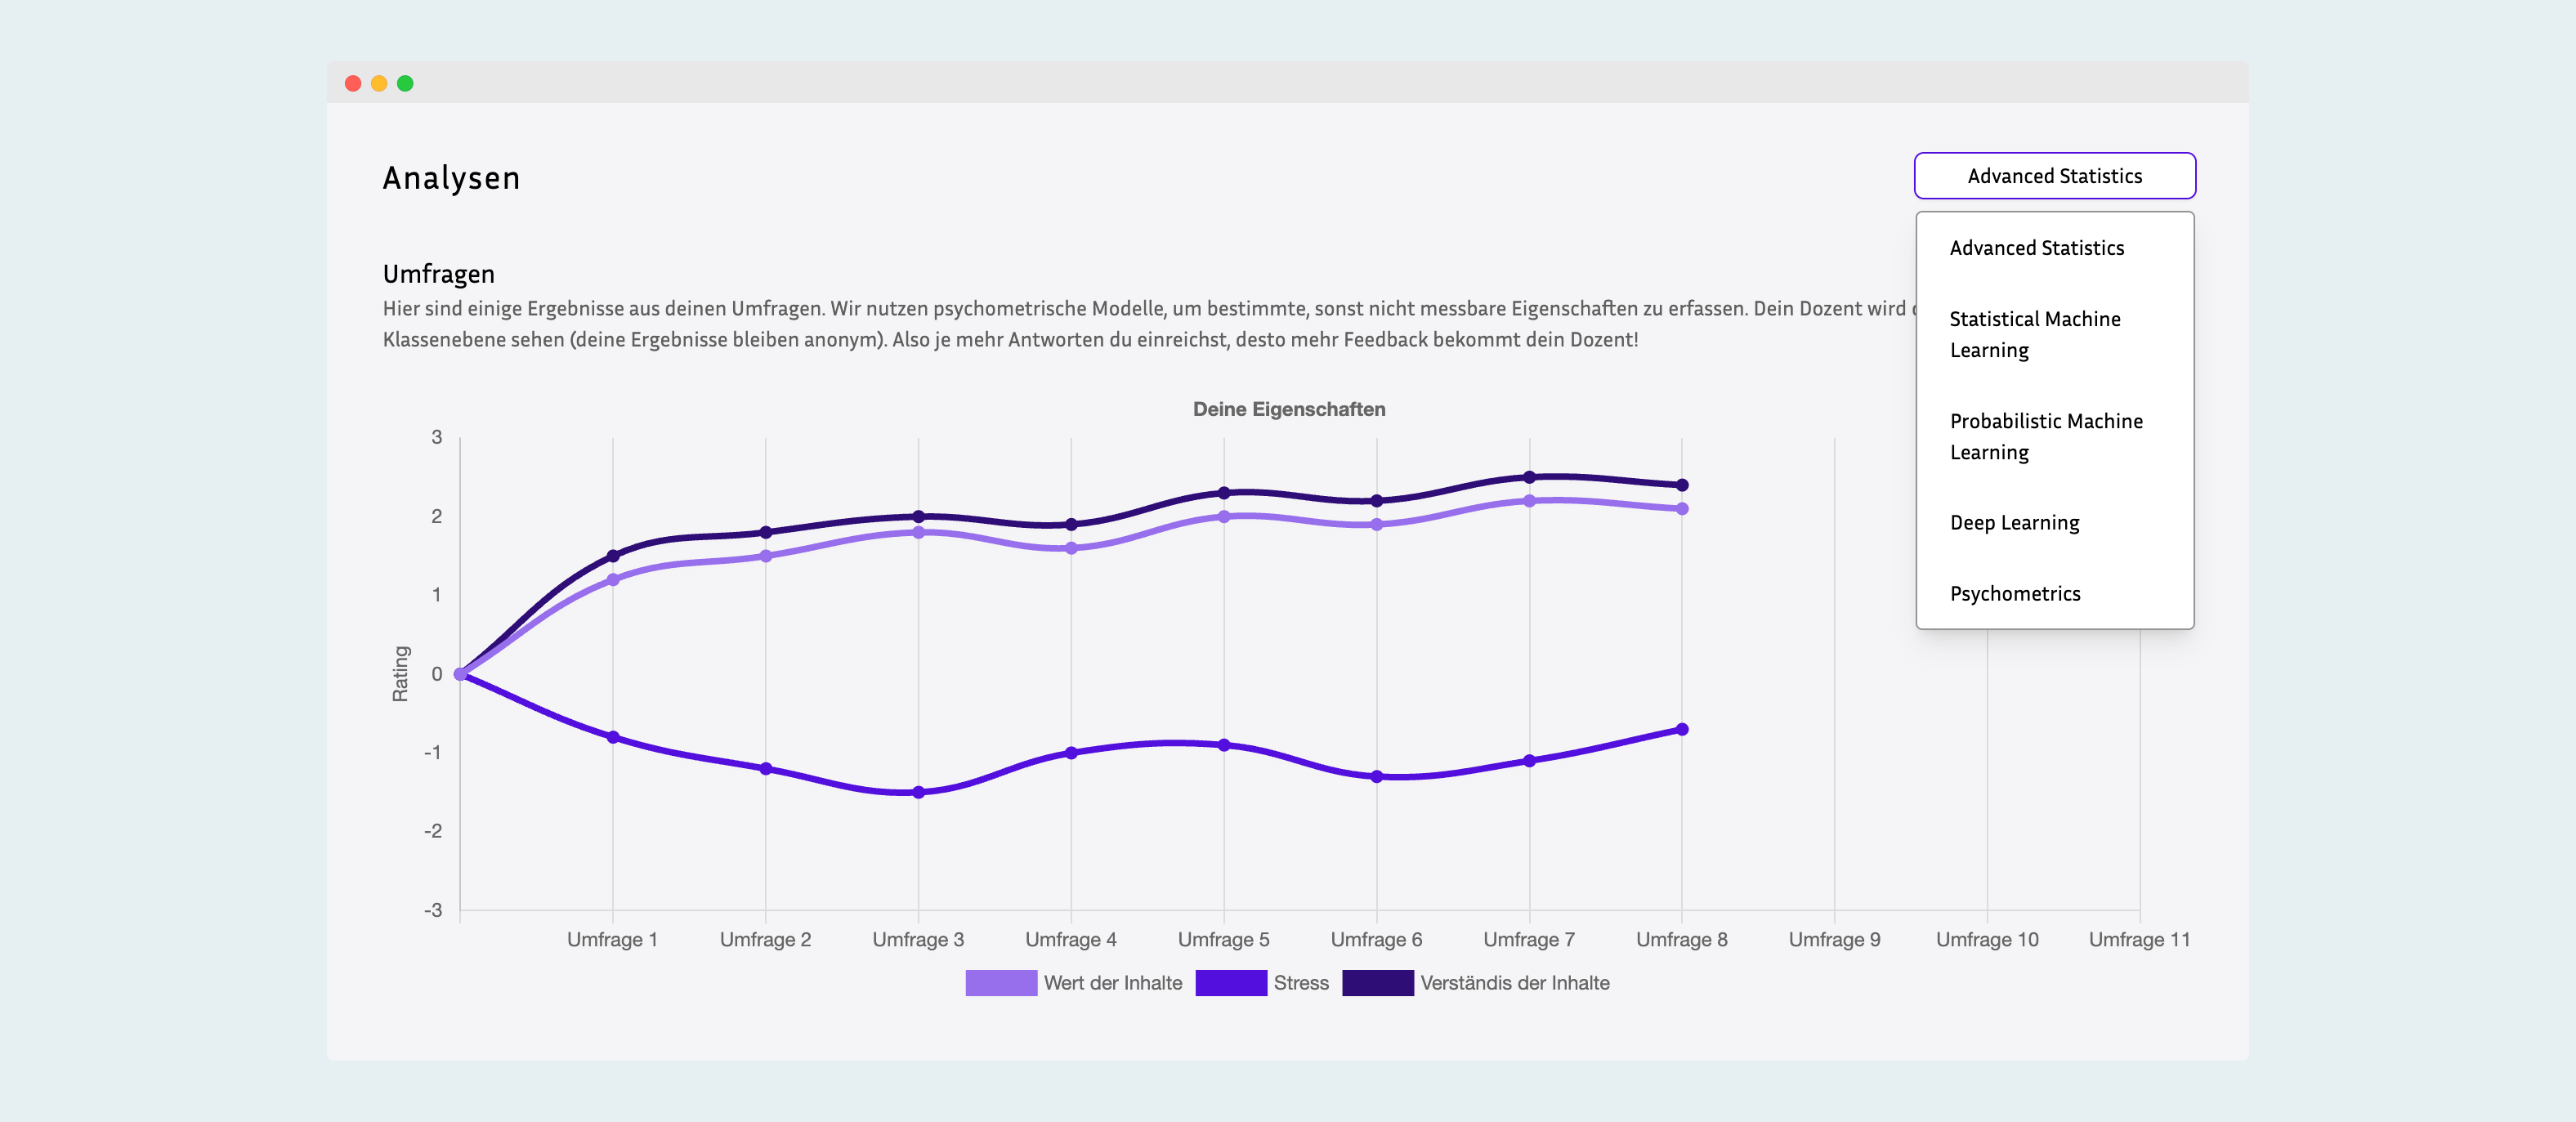 #### Access Survey Results
* Review own submitted responses (if permitted)
* Track longitudinal data collection
* Monitor engagement metrics
***
### 5. Dashboard & Navigation
#### Student Dashboard
* Central hub for all student activities
* Quick access to:
* Pending surveys
* Enrolled modules
* Recent activity
* Important notifications
#### Module-Specific Views
* Individual dashboards for each enrolled module
* Module-specific surveys and forms
* Participation history per module
***
## Student User Workflows
### Typical Student Journey
```
1. Register Account
↓
2. Complete Student Profile
↓
3. Receive Module Password from Lecturer
↓
4. Enroll in Module
↓
5. Wait for Survey Day
↓
6. Receive Survey Notification
↓
7. Fill Out Survey
↓
8. Submit Survey
↓
9. Repeat for Each Survey Period
↓
10. Complete Semester
```
### Weekly Survey Routine
```
Monday (Survey Day)
↓
Receive New StudentSurvey
↓
Login to Dashboard
↓
Navigate to Pending Surveys
↓
Open Survey Form
↓
Answer All Questions
↓
Submit Survey
↓
Survey Marked as COMPLETED
```
***
## Use Case Examples
### Use Case 1: New Student Enrollment
**Actor**: First-year mathematics student
**Steps**:
1. Receive welcome email with platform link
2. Create account with university email
3. Fill in demographic information (birth date, Abitur grade, language)
4. Receive module password from mathematics lecturer
5. Navigate to "Enroll in Module" section
6. Enter module code and password
7. Successfully enrolled in "Mathematics I - Winter Semester"
**Outcome**: Student is now enrolled and will receive surveys on configured days
***
### Use Case 2: Completing Weekly Survey
**Actor**: Enrolled student
**Steps**:
1. Receive notification on Monday (survey day)
2. Login to platform
3. See "1 Pending Survey" on dashboard
4. Click on survey for "Mathematics I"
5. Answer questions about:
* Current emotional state
* Study hours this week
* Difficulty level of material
* Confidence in understanding
6. Click "Submit Survey"
7. Receive confirmation message
**Outcome**: Survey marked as completed, data stored in StudentSurvey JSON content
***
### Use Case 3: Tracking Progress
**Actor**: Student mid-semester
**Steps**:
1. Navigate to "My Modules" section
2. Select "Mathematics I" module
3. View survey history:
* Survey #1 (Week 1): Completed ✓
* Survey #2 (Week 2): Completed ✓
* Survey #3 (Week 3): Not Completed ✗
* Survey #4 (Week 4): Completed ✓
4. See completion rate: 75% (3/4 surveys)
5. Review submission dates and times
**Outcome**: Student aware of participation status and can plan accordingly
***
### Use Case 4: Managing Multiple Modules
**Actor**: Student enrolled in multiple courses
**Steps**:
1. Enrolled in:
* Mathematics I (Mondays & Thursdays)
* Statistics (Wednesdays)
* Linear Algebra (Fridays)
2. Dashboard shows separate survey counters per module
3. Complete surveys for each module on respective days
4. Track progress independently for each course
**Outcome**: Organized participation across multiple modules
***
### Use Case 5: Updating Profile Information
**Actor**: Returning student
**Steps**:
1. Navigate to profile settings
2. Update financial support status (received scholarship)
3. Update preferred language setting
4. Add nickname for informal communications
5. Save changes
**Outcome**: Profile updated, information available for research analysis
***
## Student Capabilities Summary
### What Students Can Do:
✅ **Account & Profile**
* Create and verify account
* Manage personal information
* Update profile details
* Change credentials
✅ **Module Management**
* Browse available modules
* Enroll with password
* View enrolled modules
* Access module details
✅ **Survey Interaction**
* Receive scheduled surveys
* Fill out survey forms
* Submit responses
* Track completion status
✅ **Data Viewing**
* View survey history
* See completion rates
* Track participation
* Monitor progress
✅ **Dashboard**
* Access centralized dashboard
* View pending tasks
* Navigate modules
* See notifications
### What Students Cannot Do:
❌ Create or modify modules
❌ Access other students' data
❌ Change survey schedules
❌ Delete submitted surveys
❌ View aggregated analytics
❌ Manage lecturer functions
❌ Access admin features
***
## Student Interface Components
### Key Pages/Views:
1. **Login/Registration Page**
2. **Student Dashboard** (Main Hub)
3. **Profile Management Page**
4. **Module Enrollment Page**
5. **Enrolled Modules List**
6. **Survey Form Page**
7. **Survey History Page**
8. **Module Details Page**
### Dashboard Widgets:
* **Pending Surveys** - Quick access to incomplete surveys
* **Enrolled Modules** - List of active enrollments
* **Recent Activity** - Latest survey submissions
* **Completion Statistics** - Progress tracking
***
## Benefits for Students
### Academic Benefits
* Structured participation in research
* Self-awareness of learning patterns
* Regular reflection on academic progress
* Contribution to educational improvement
### User Experience Benefits
* Simple, intuitive interface
* Clear task management
* Progress tracking
* Organized survey workflow
### Privacy & Security
* Secure authentication
* Protected personal data
* Controlled data access
* Research ethics compliance
***
For technical details, see [Architecture Guide](./architecture.md)
For installation, see [Installation Guide](./installation.md)
For lecturer features, see [Lecturer Experience](./lecturer-experience.md)